
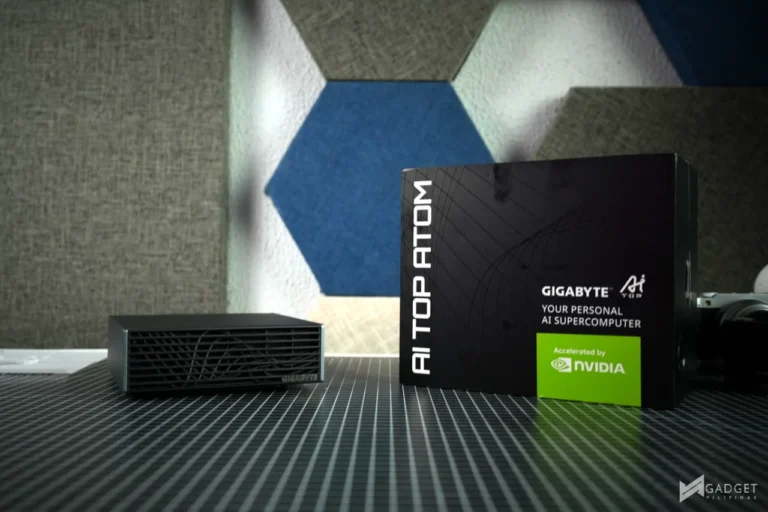
Over the past two years, the industry narrative around AI has been dominated by the push for the cloud. For small development teams, independent researchers, creative studios, and business that meant tanking the cost of monthly token billing, API rate limits, and constant data privacy trade-offs. While consumer desktop hardware has tried to bridge the gap with high-VRAM enthusiast cards, enterprise-grade model fine-tuning and heavy local deployment still demand dedicated GPUs and a scalable setup. Enter the DGX Spark powered by the NVIDIA GB10 Grace Blackwell superchip, positioned directly at local AI builders, researchers, and studio workloads. In typical NVIDIA fashion, partner brands have their own designs and our specific unit in this review is the GIGABYTE AI TOP ATOM DGX Spark.
GIGABYTE AI TOP ATOM DGX SPARK – A Closer Look
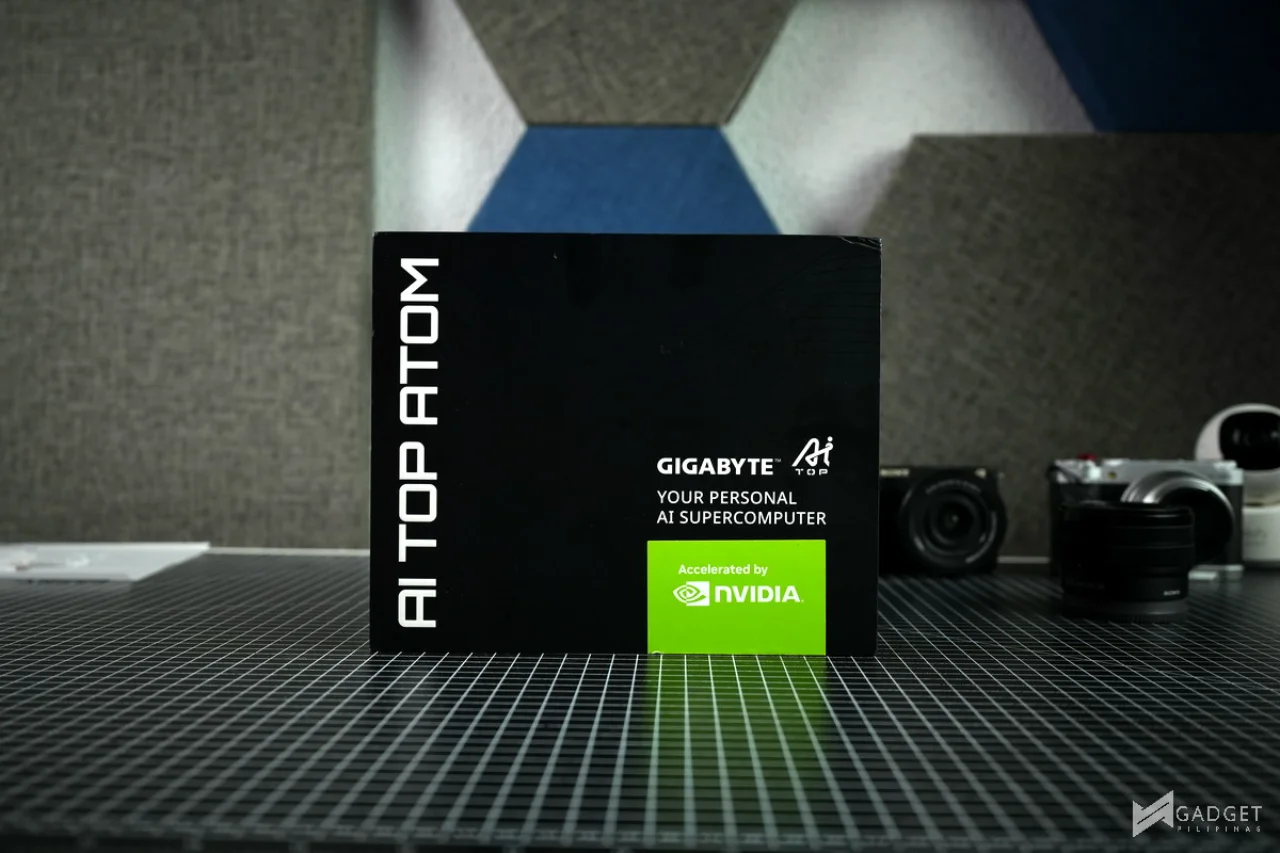
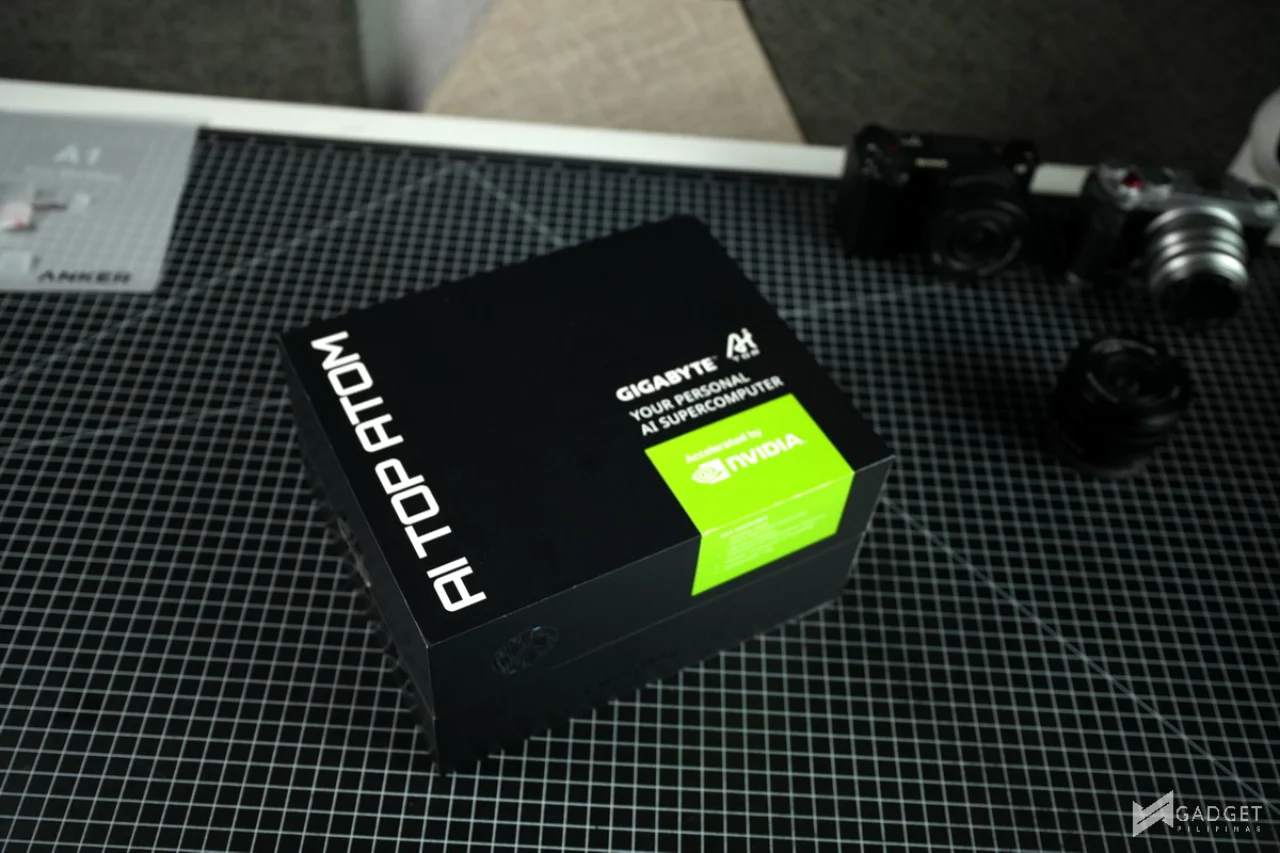
Packaging of the Gigabyte AI TOP ATOM is simple and follow’s NVIDIA’s own DGX Spark packaging layout.
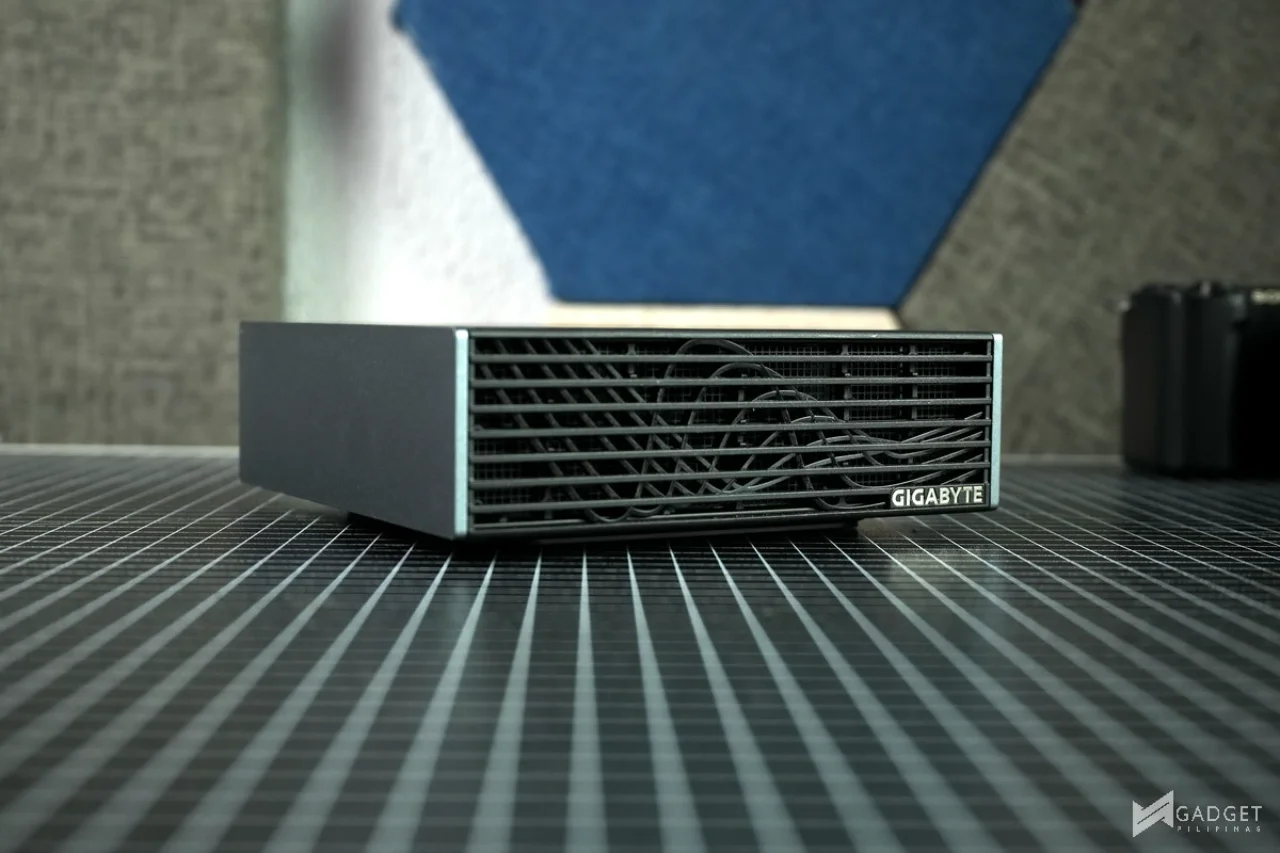
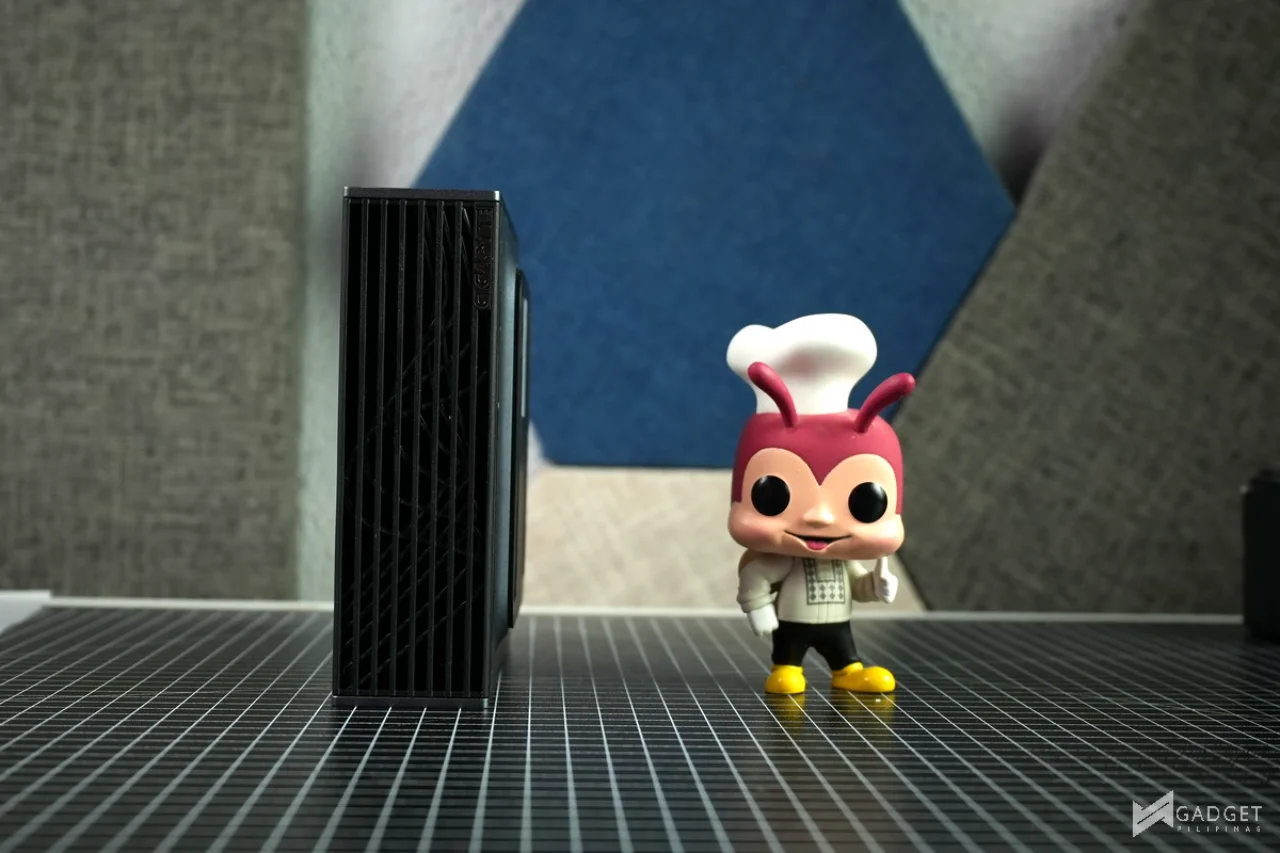
The Gigabyte AI TOP ATOM features a front mesh design. Like the rest of the DGX Sparks, it follows the standard 150mm x 150mm x 50mm (W x D x H) form factor.
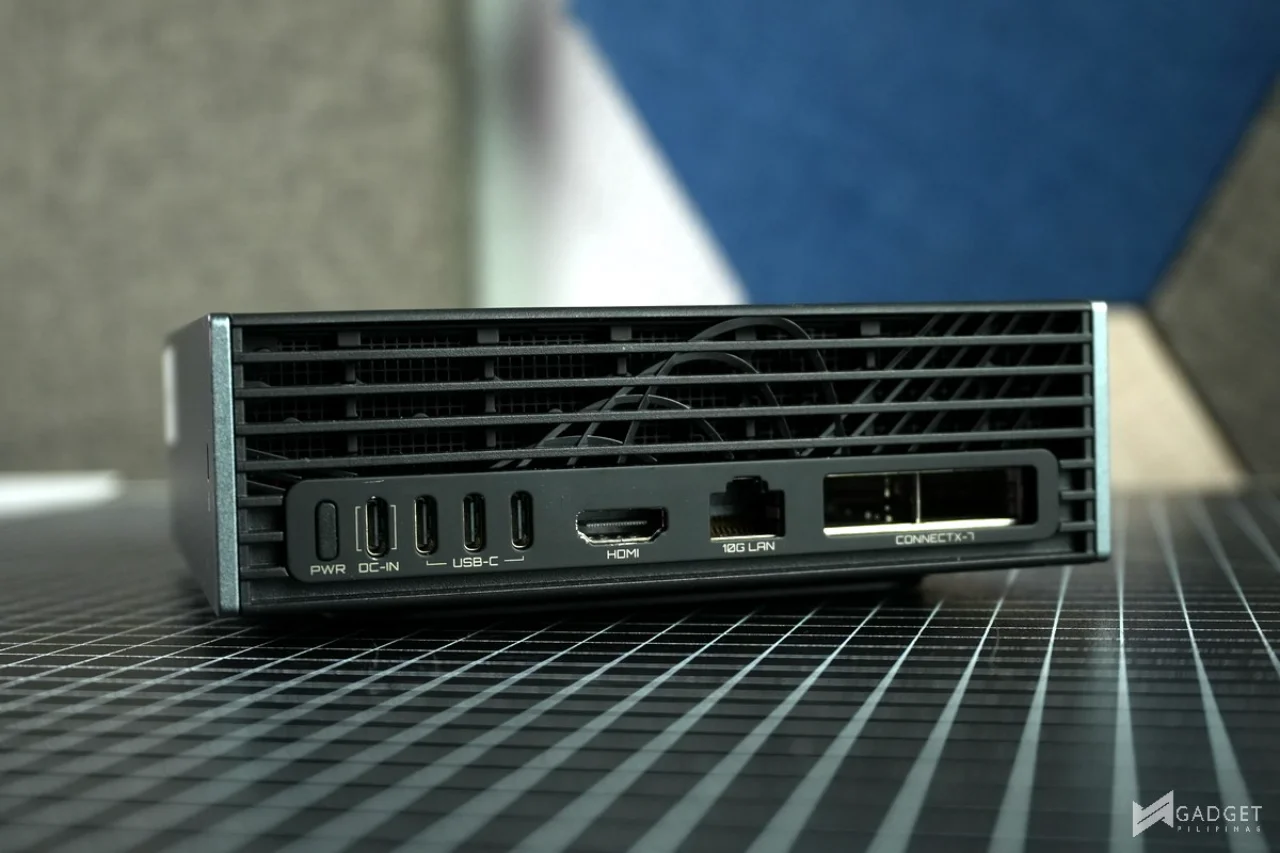
IO configuration is standard across all DGX Spark variants, One USB Type-C port is solely dedicated for power, three more USB 3.2 Type-C ports for connectivity, an HDMI 2.1a port, one RJ45 10G Ethernet port, and one QSFP112 400Gbps port or the NVIDIA ConnectX-7 port.
The Connect X-7 port is an exclusive feature to the DGX Spark platform that the RTX Spark version doesn’t have. CONNECT X-7 lets you cluster up to four DGX Spark for a total of 512GB unified memory which can support up to 700 billion parameter models.
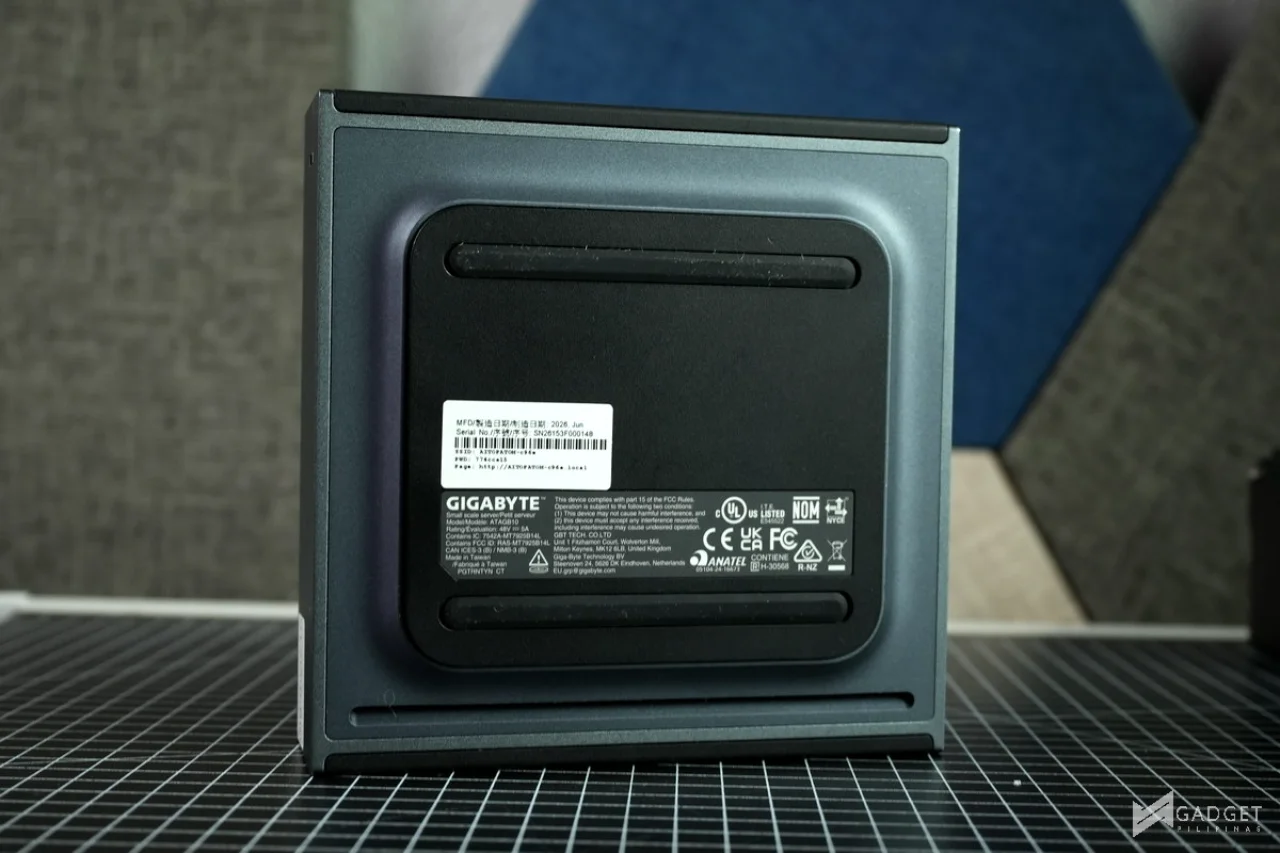
The DGX Spark’s storage is the only upgradable component and it’s not as easily accessible compared to your standard miniPCs. For the AI TOP ATOM, upgrading the Gen4 or Gen5 SSD requires you to pry open the stand which also exposes the wifi module. Gigabyte does not encourage end-user upgrades and recommends purchasing the desired storage option out of the box as these SSDs come with hardware level encryption.
DGX Spark Hardware Architecture & Platform Overview
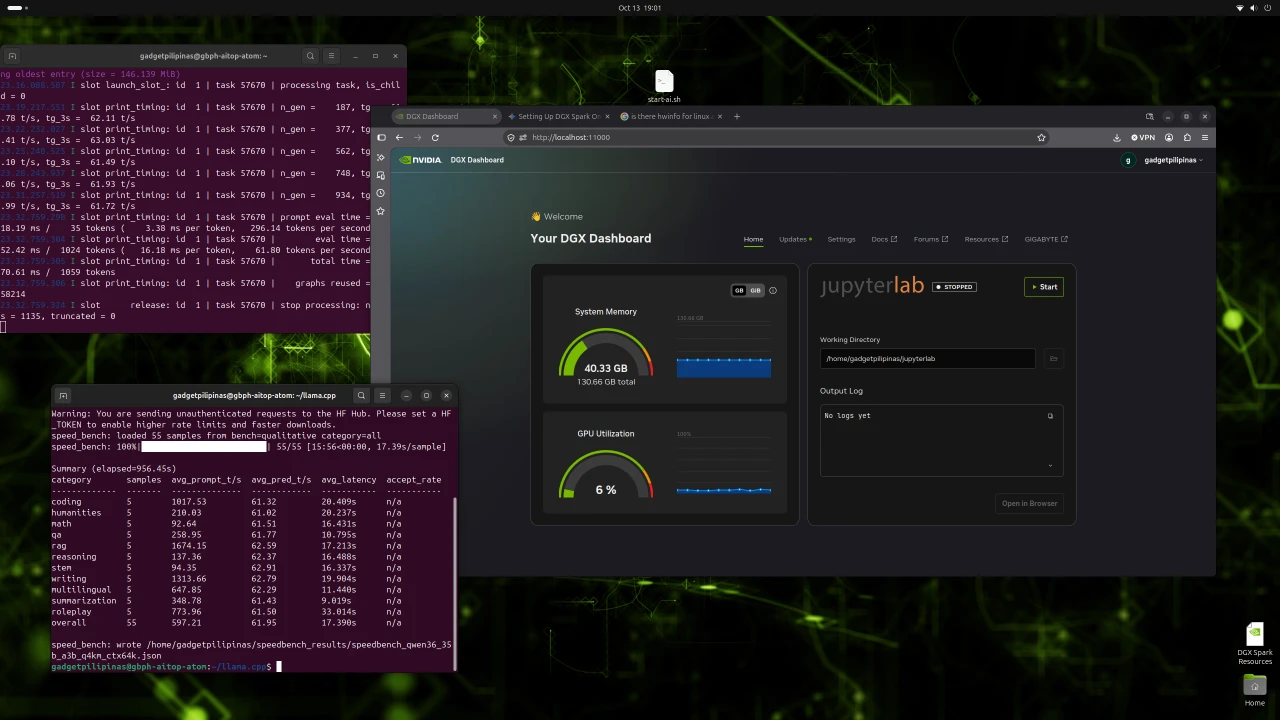
The NVIDIA DGX Spark platform runs the NVIDIA DGX OS, a customized, Ubuntu-based Linux distribution. It comes with pre-installed tools namely the DGX Dashboard, NVIDIA AI Workbench, Jupyter Lab updated to CUDA 13 and PyTorch, Docker container runtimes, and NVIDIA NGC Access.
Benchmark Setup and Test Methodology
Gadget Pilipinas’ testing philosophy is to provide detail-oriented results as accurately as possible so that our readers can replicate our tests, given that these conditions are met. Different benchmarking apps and sequences are used depending on the component or device being tested.
For our DGX Spark benchmarks, we chose Qwen 3.8 27B UD Q4_K_M and Qwen 3.6 35B-A3B Q4_K_M models across a wide suite of AI benchmarks. Qwen 3.8 represents mid-sized dense models while the older Qwen 3.6 35B-A3B represents spars Mixture-of-Expert(MoE models). Both models are large for normal 12-16GB consumer cards while the higher 24-32GB GPUs not being able to maximize both model’s 262,144 token native context window without quantizations. Both models share the same native context window, hybrid Gated DeltaNet linear-attention backbone, the same multimodal vision capabilities, and built-in Multi-Token Prediction (MTP) heads for self-speculative decoding.
GIGABYTE AI TOP ATOM DGX SPARK AI Benchmarks
llama benchy
llama benchy focuses on simulated real-world conversational inference and end-to-end pipeline latency bridging the gap between synthetic CLI tests and real-world API serving, allowing fair, apples-to-apples comparisons across any OpenAI-compatible inference engine while actively testing context caching and speculative decoding. This benchmark gives developers an accurate picture of the user-facing responsiveness they can expect when deploying interactive chat interfaces or local assistant backends
It evaluates continuous streaming performance, measuring time-to-first-token (TTFT) latency, inter-token jitter (consistency of generation speed without micro-stutters), and context-window degradation as multi-turn conversational history expands.
llama.cpp Benchmark
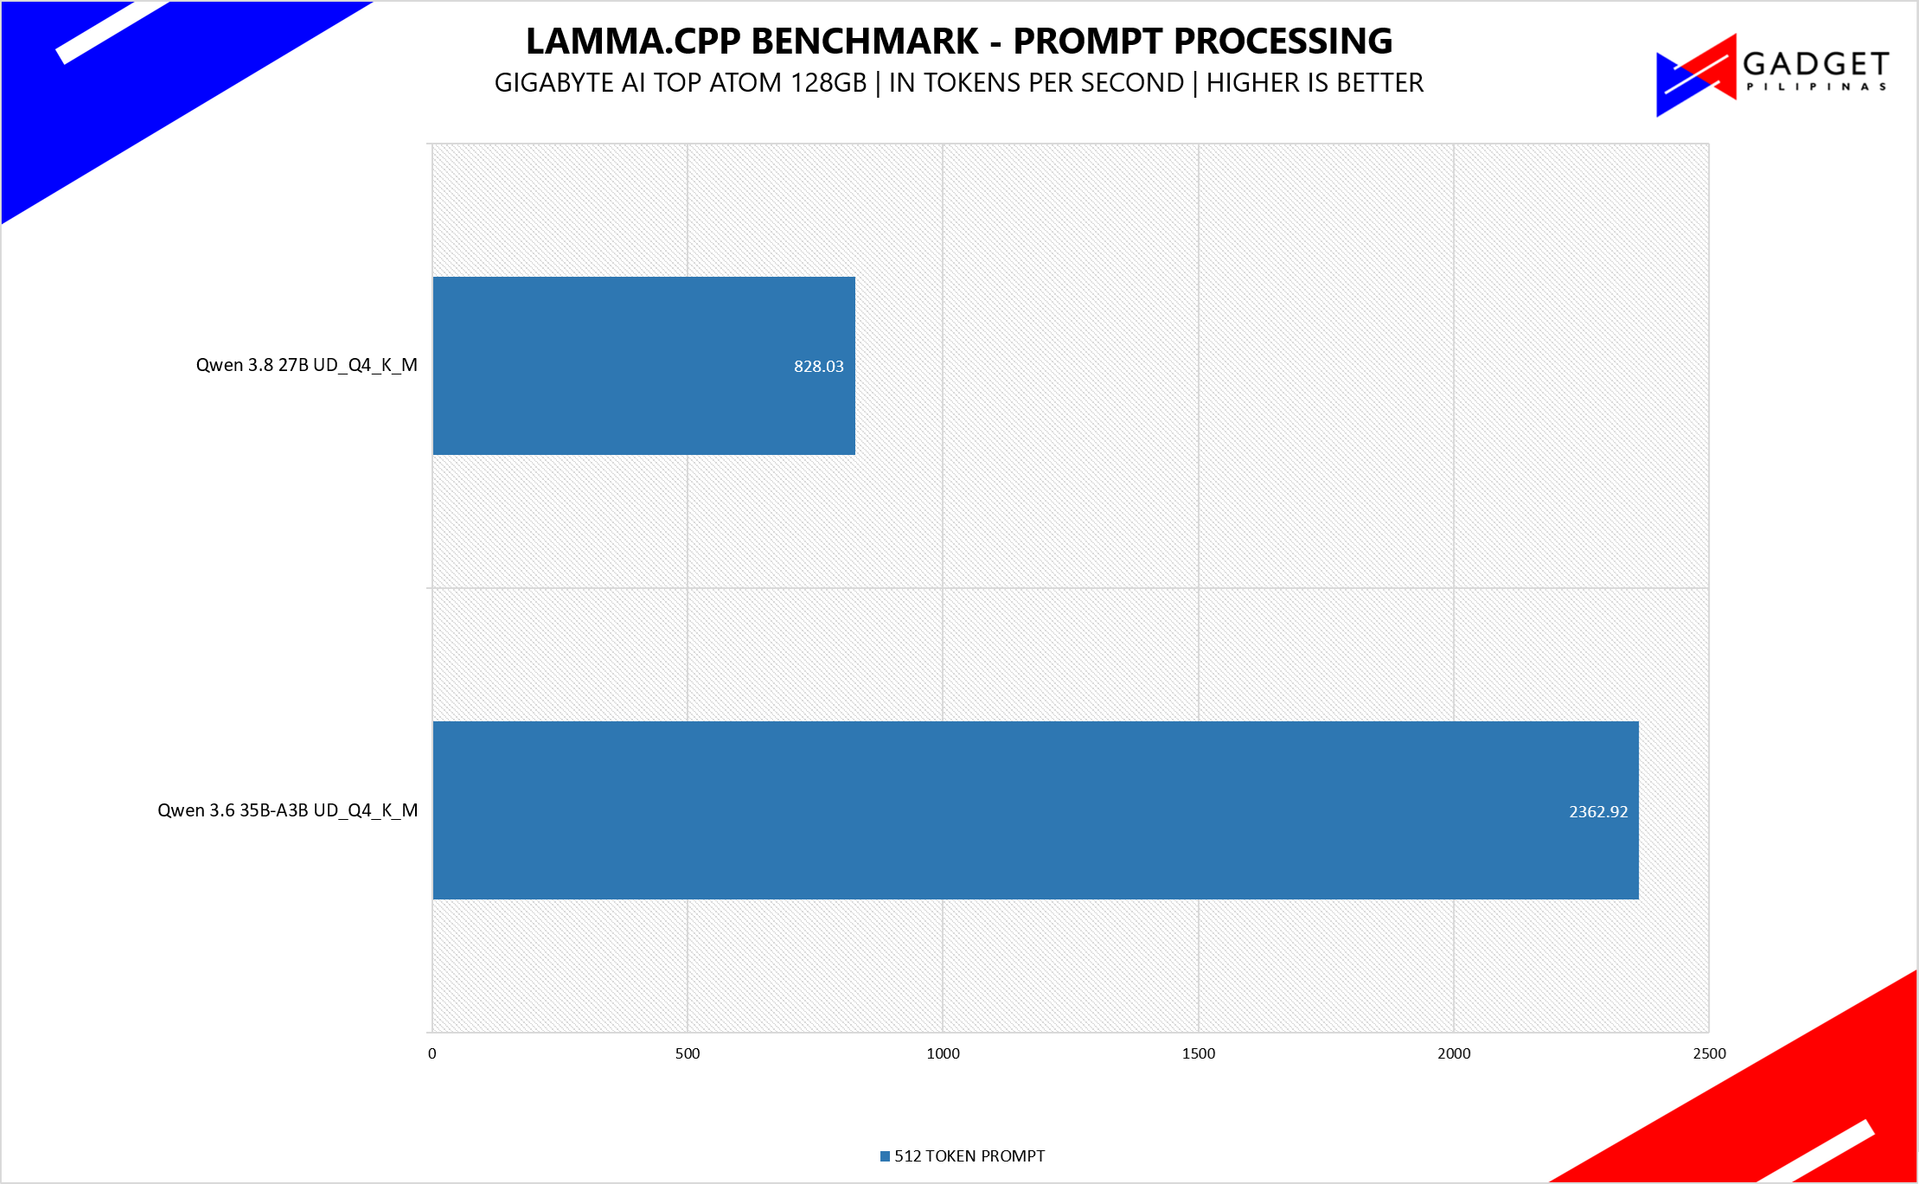
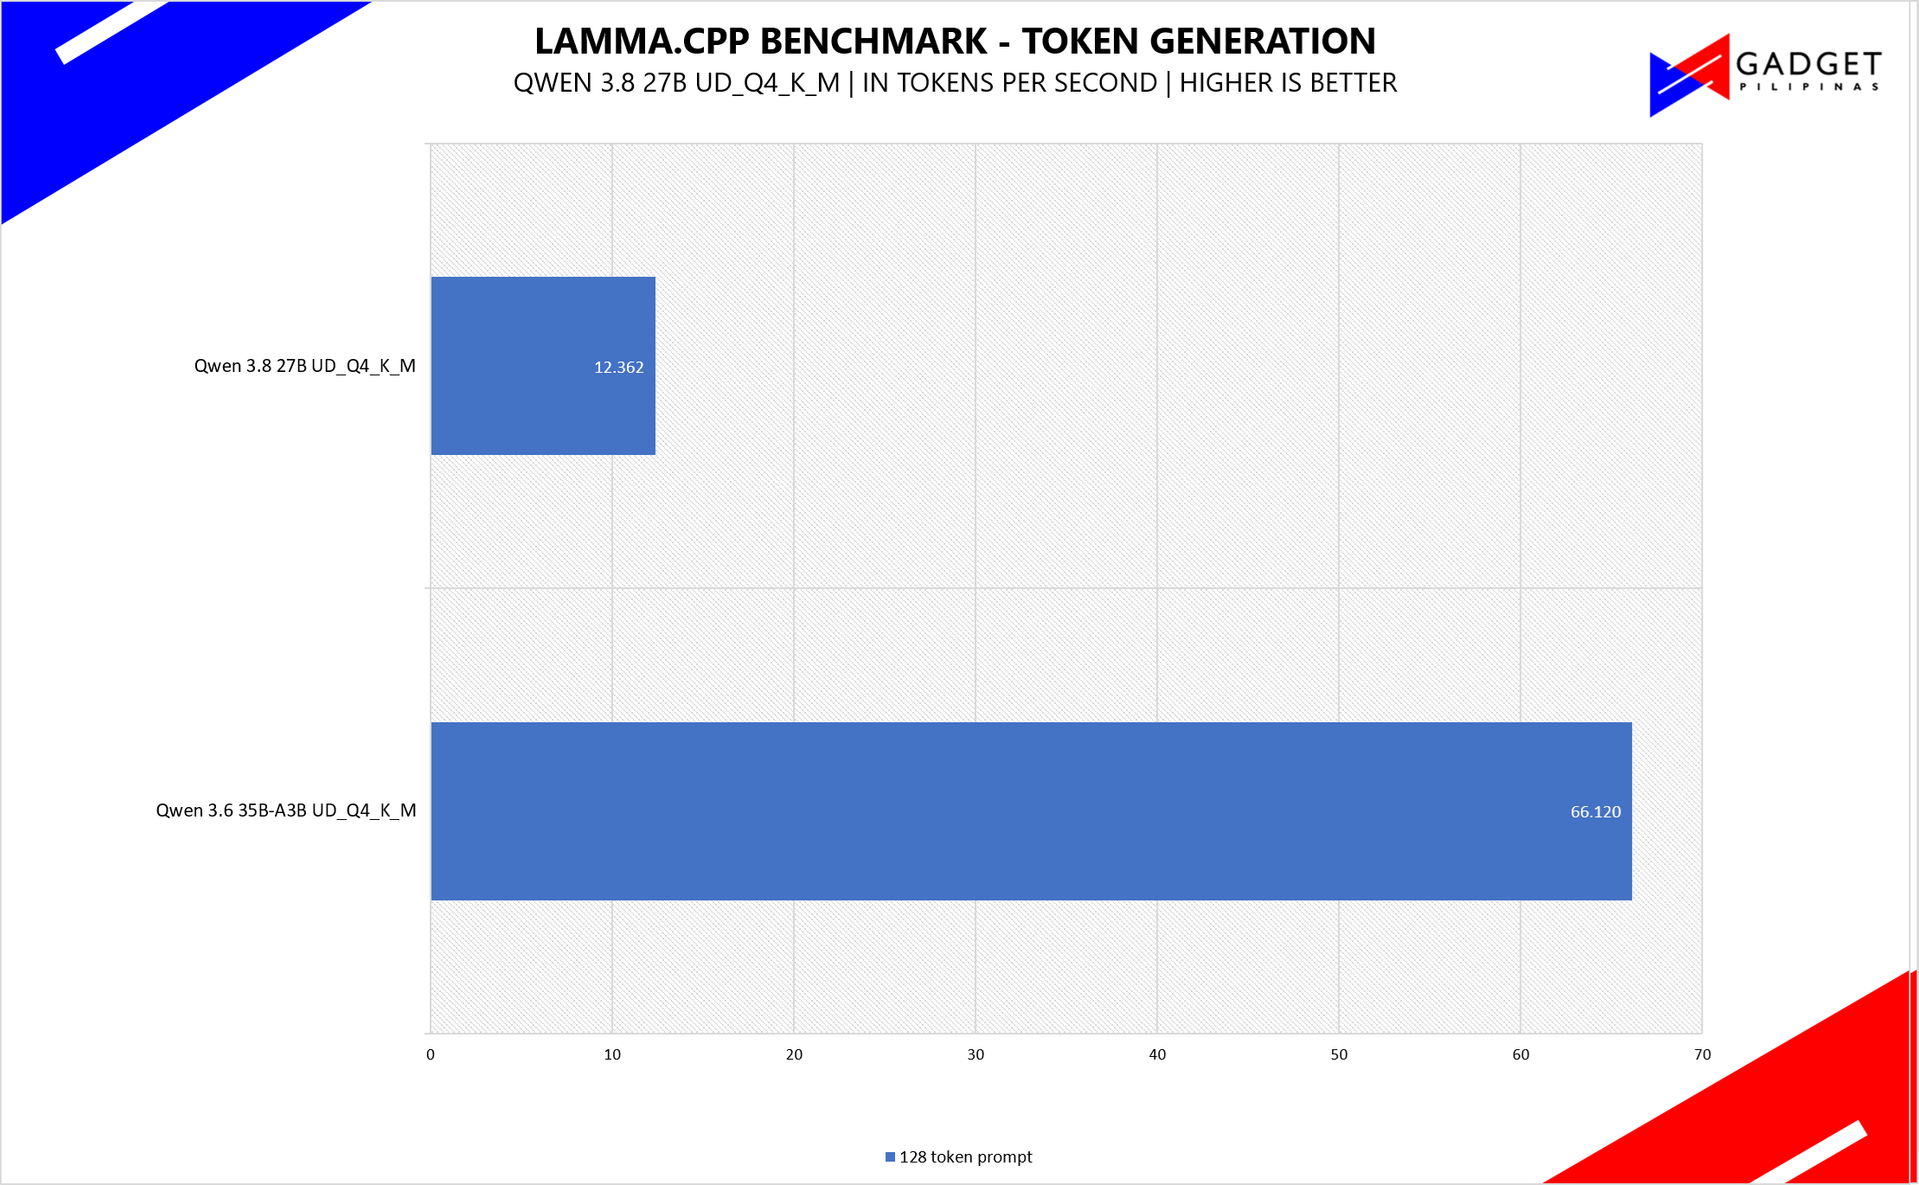
llama Bench is the foundational standard for measuring low-level raw tensor processing performance. It directly measures uncontended Prompt Processing (pp) speed in tokens per second and Token Generation (tg) speed in tokens per second across isolated batch sizes, thread counts, and GGUF quantization tiers. By sweeping across common quantization formats and variable batch sizes, it reveals memory bandwidth saturation and raw compute efficiency without overhead from API layers or UI wrappers.
Agent Perf
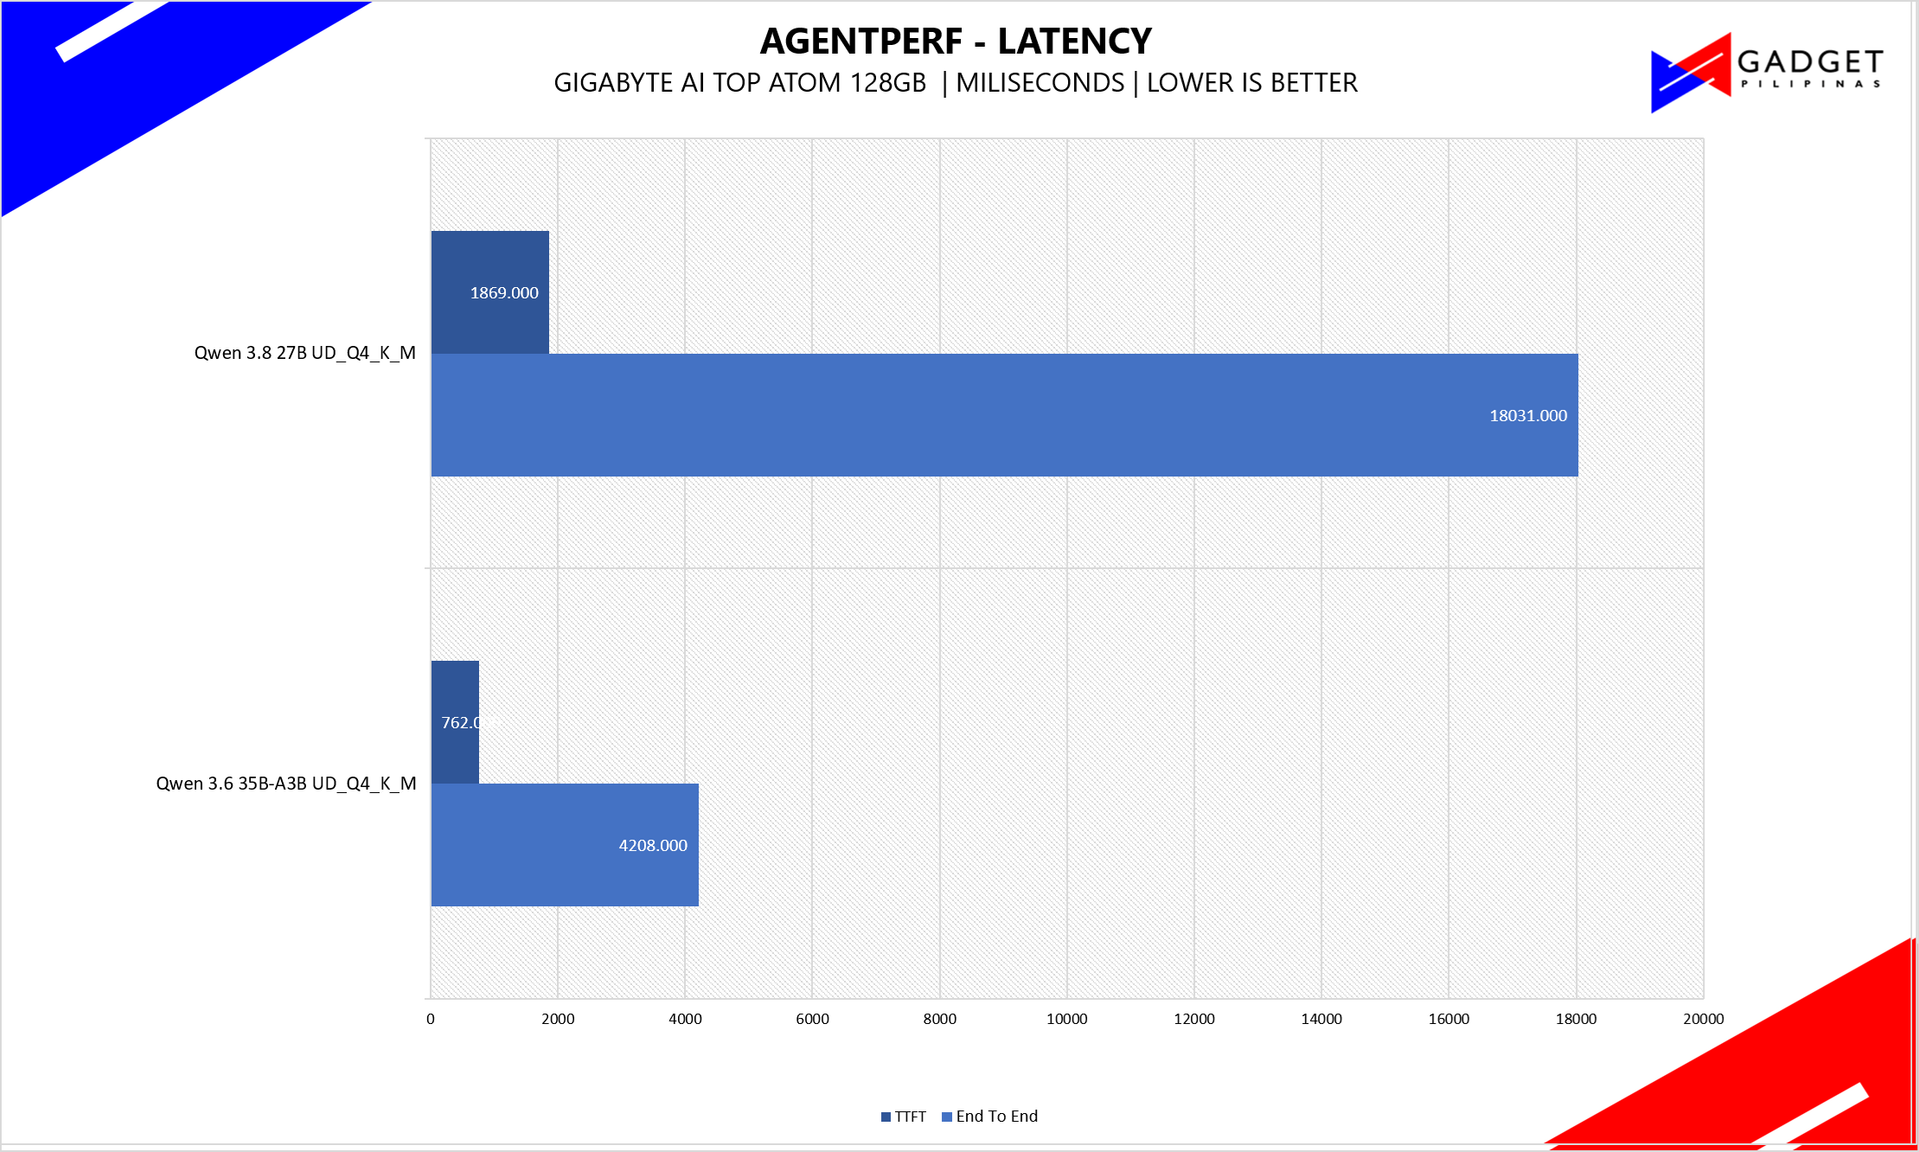
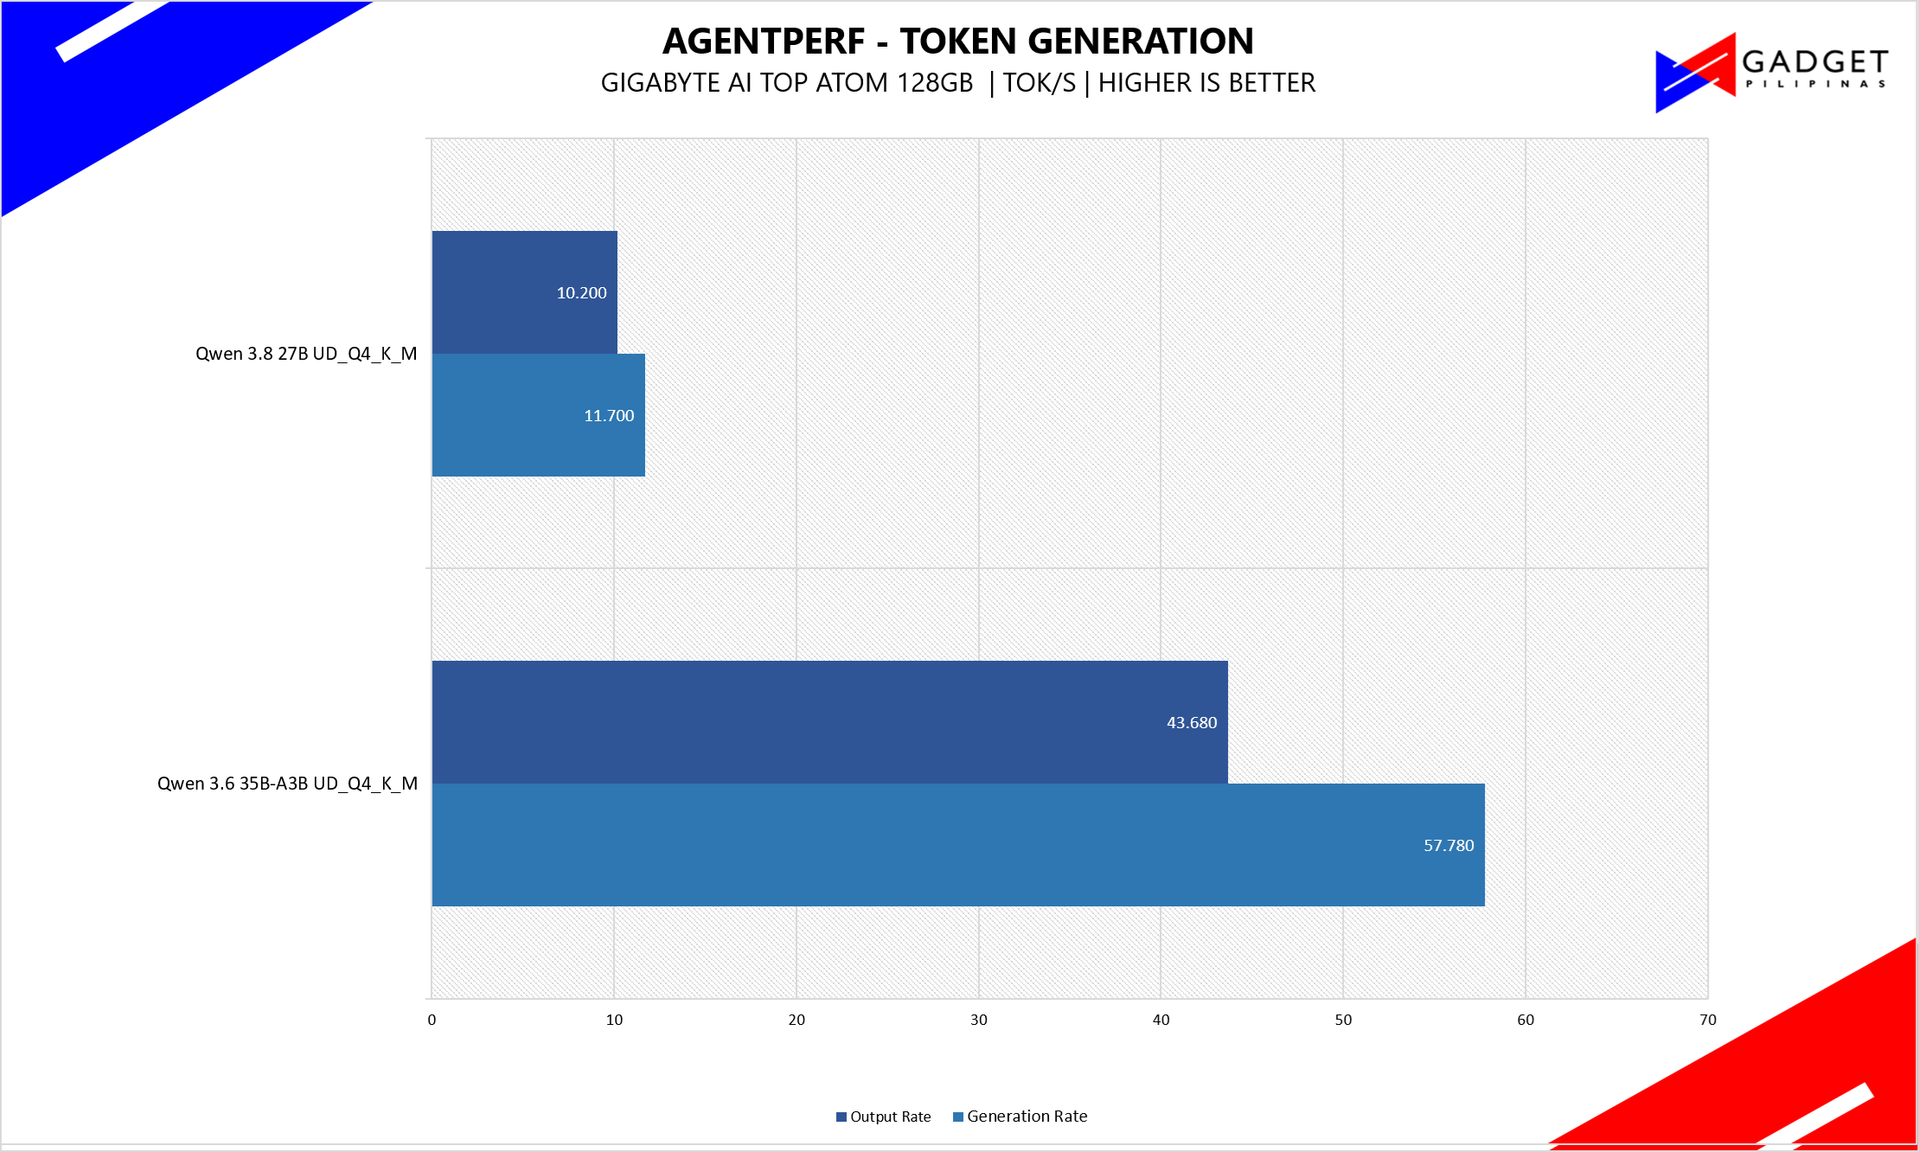
Agent Perf benchmark measures the system’s ability to handle complex, multi-step agentic workflow including tool-use and function-calling latency, structured JSON output reliability, context-switching speed, and end-to-end task completion times across iterative problem-solving loops (such as code interpretation, API calling, and autonomous data extraction). Agent Perf tests whether the system can handle frequent context re-evaluations without choking on overhead.
Speedbench
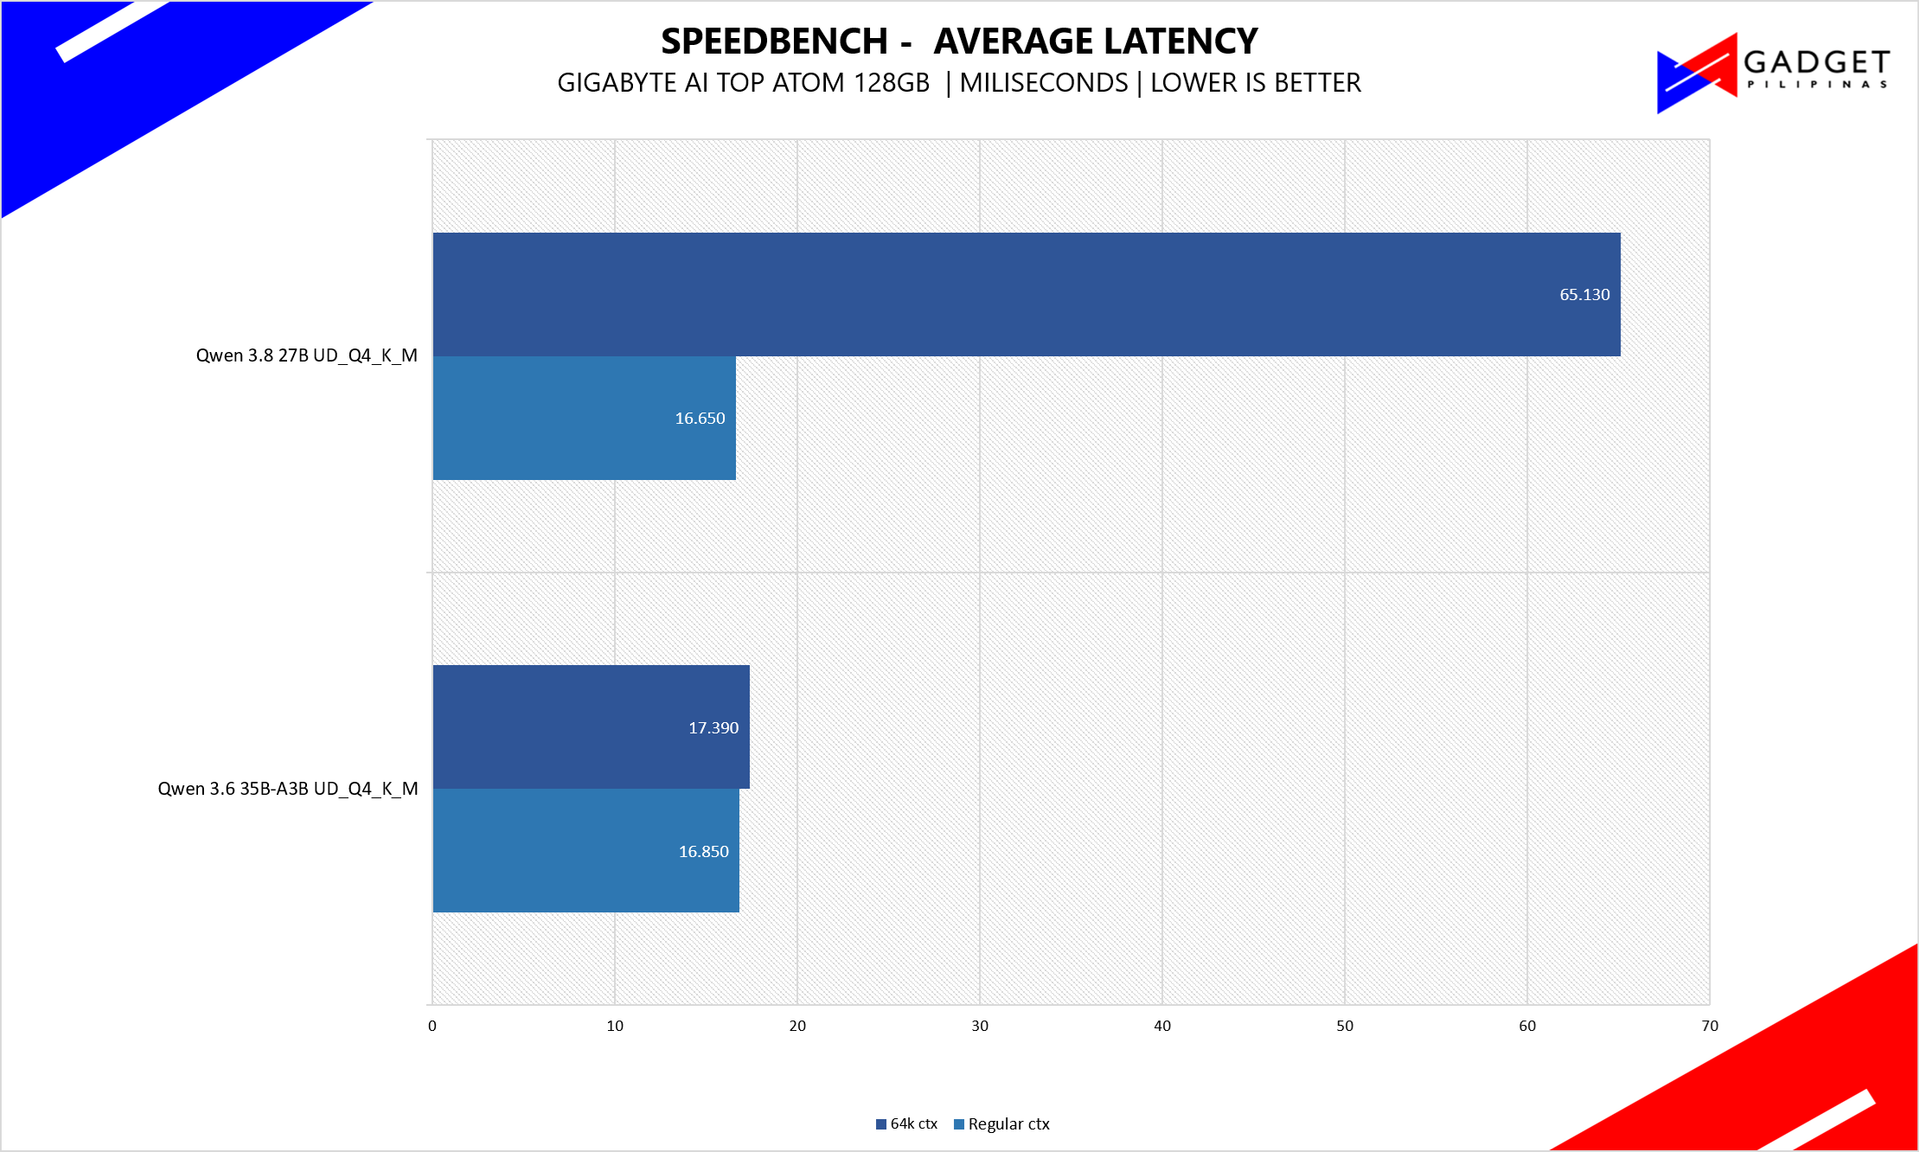
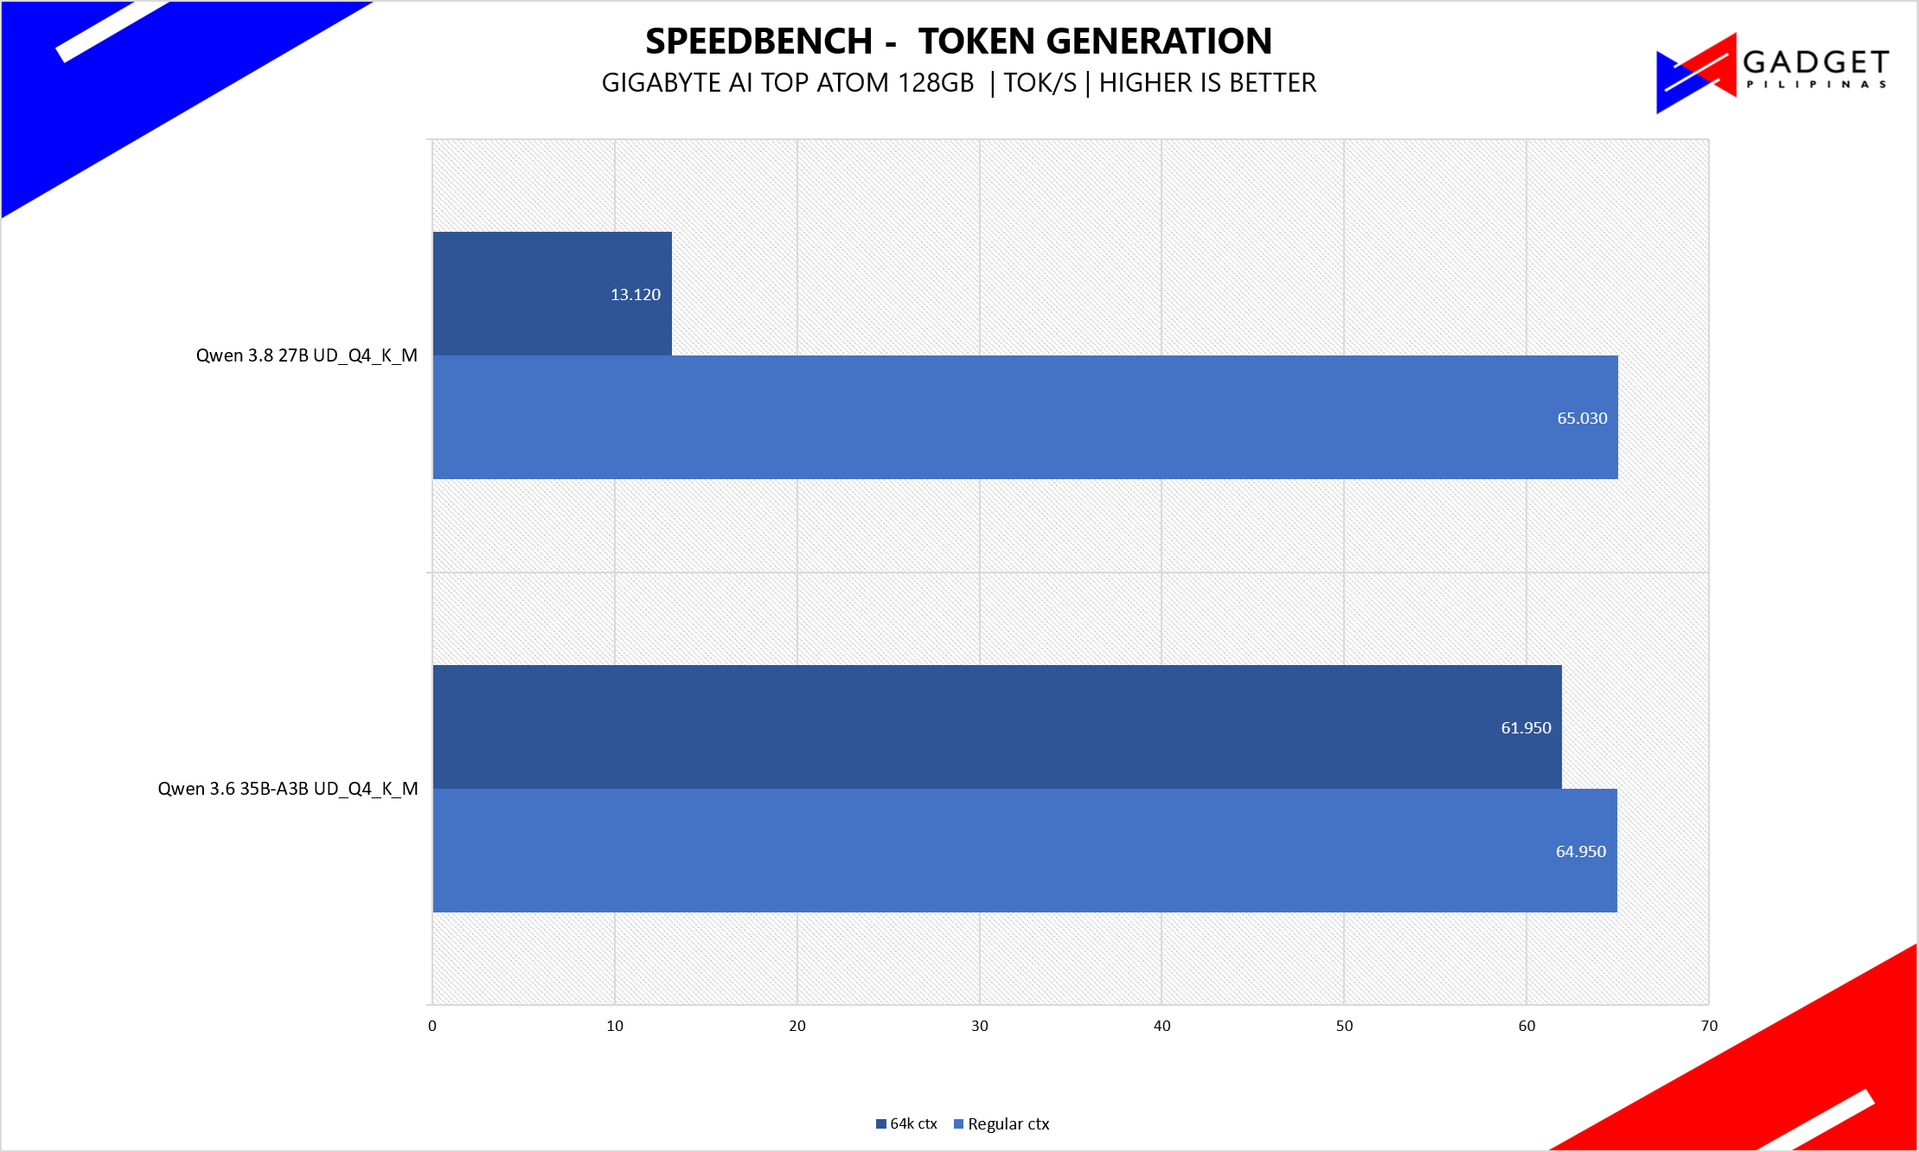
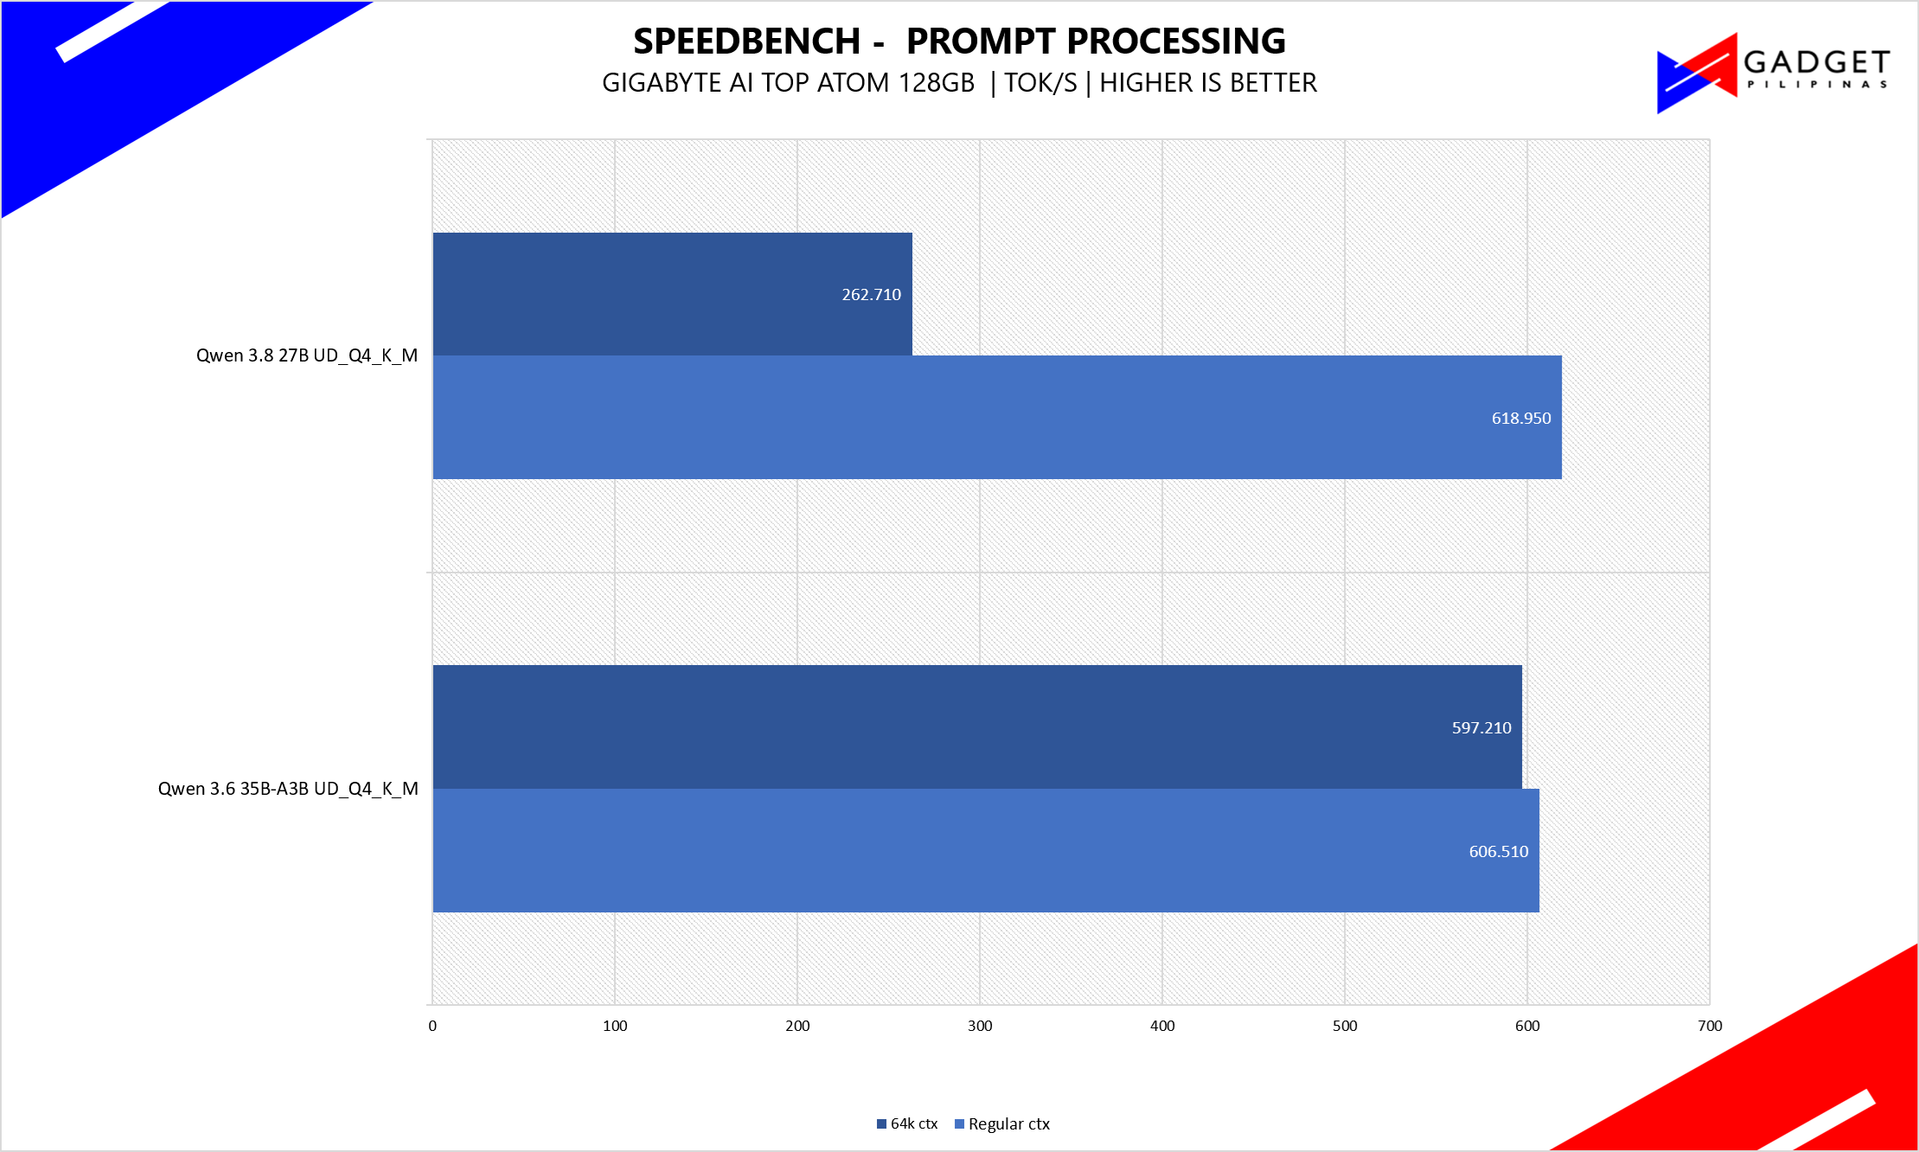
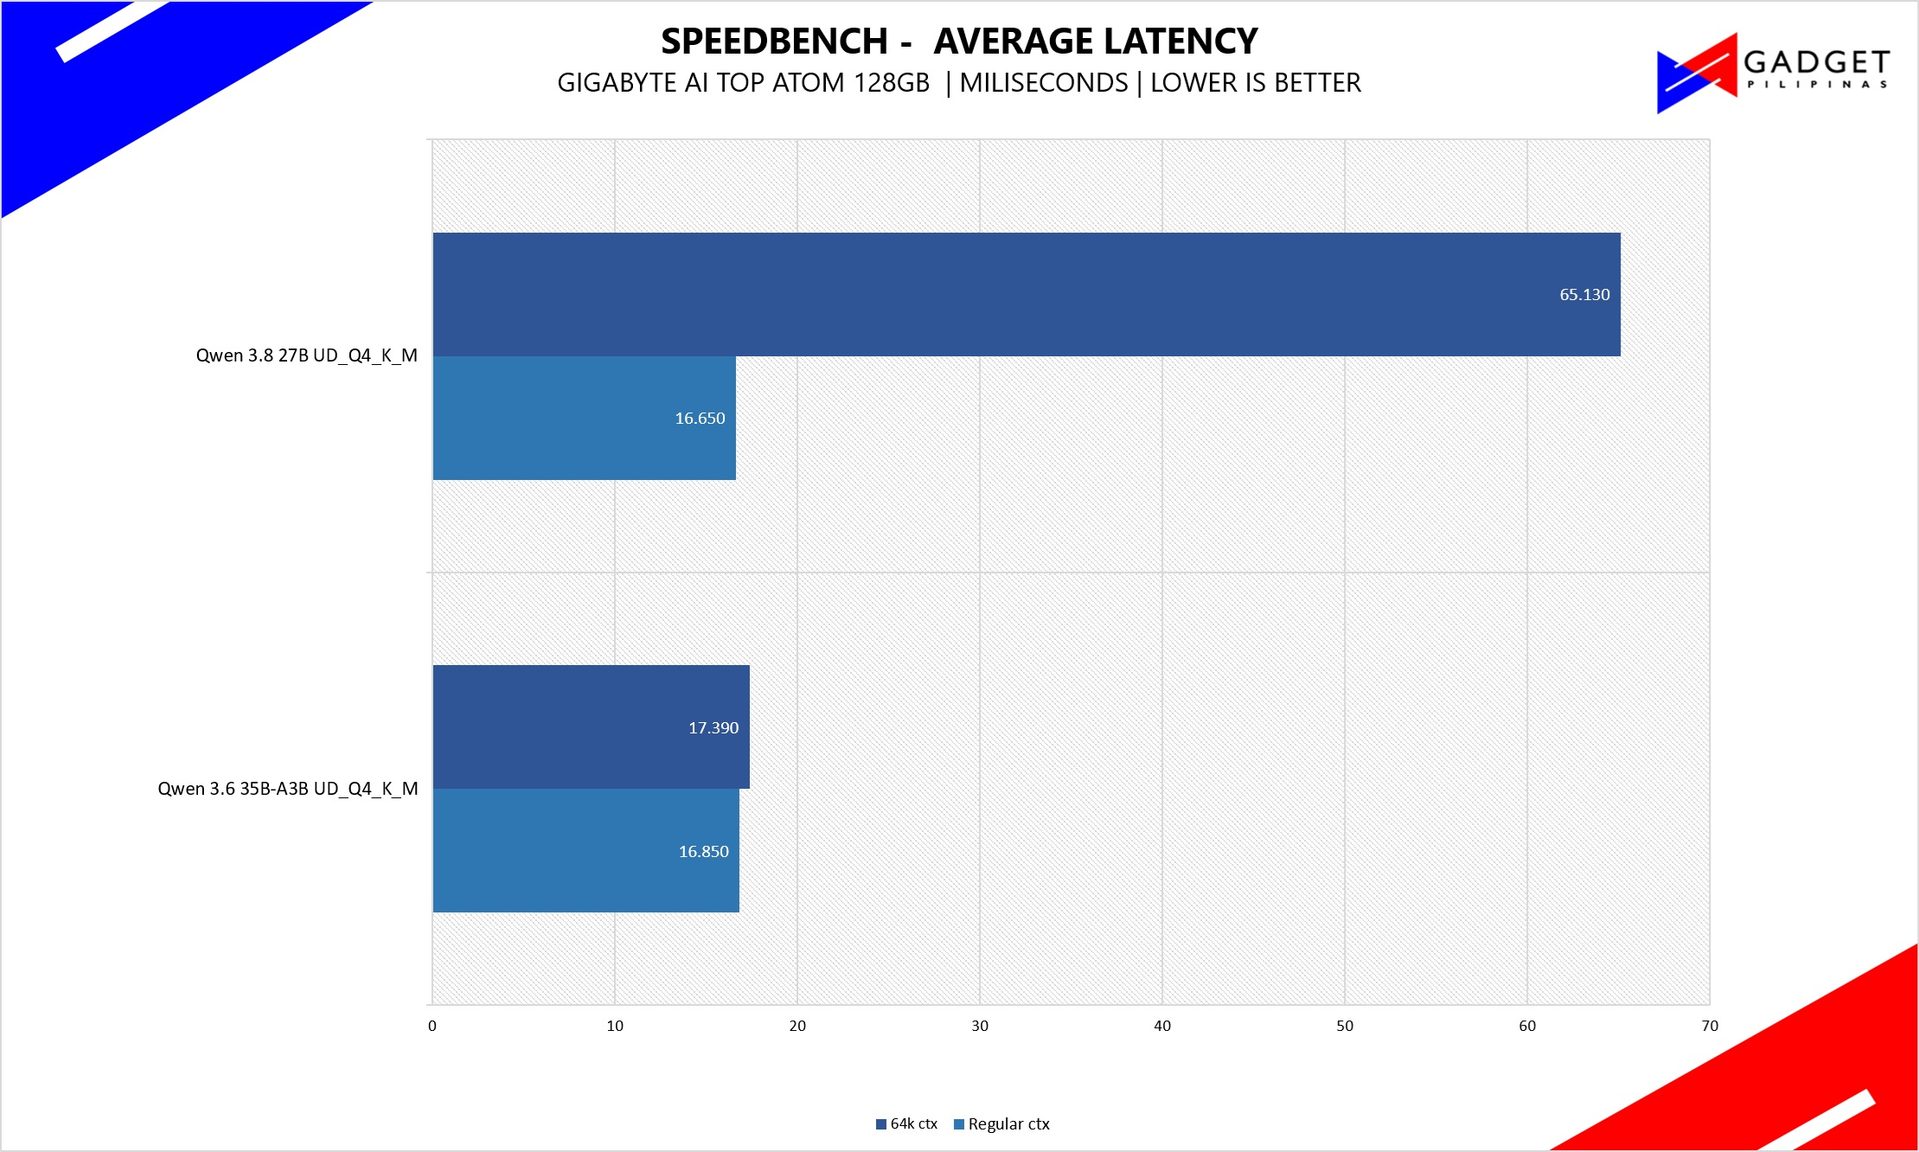
Speedbench is designed to stress-test peak hardware throughput and batch execution limits. Rather than simulating a single conversational user, Speedbench hammers the acceleration pipeline with concurrent inference batches and rapid prompt queues. It measures model compilation times (where applicable), kernel dispatch latency, memory allocation overhead, and total aggregate token generation per second across sustained heavy loads. It serves as the primary metric for evaluating multi-user local serving or high-volume batch data processing.
LLMPerf
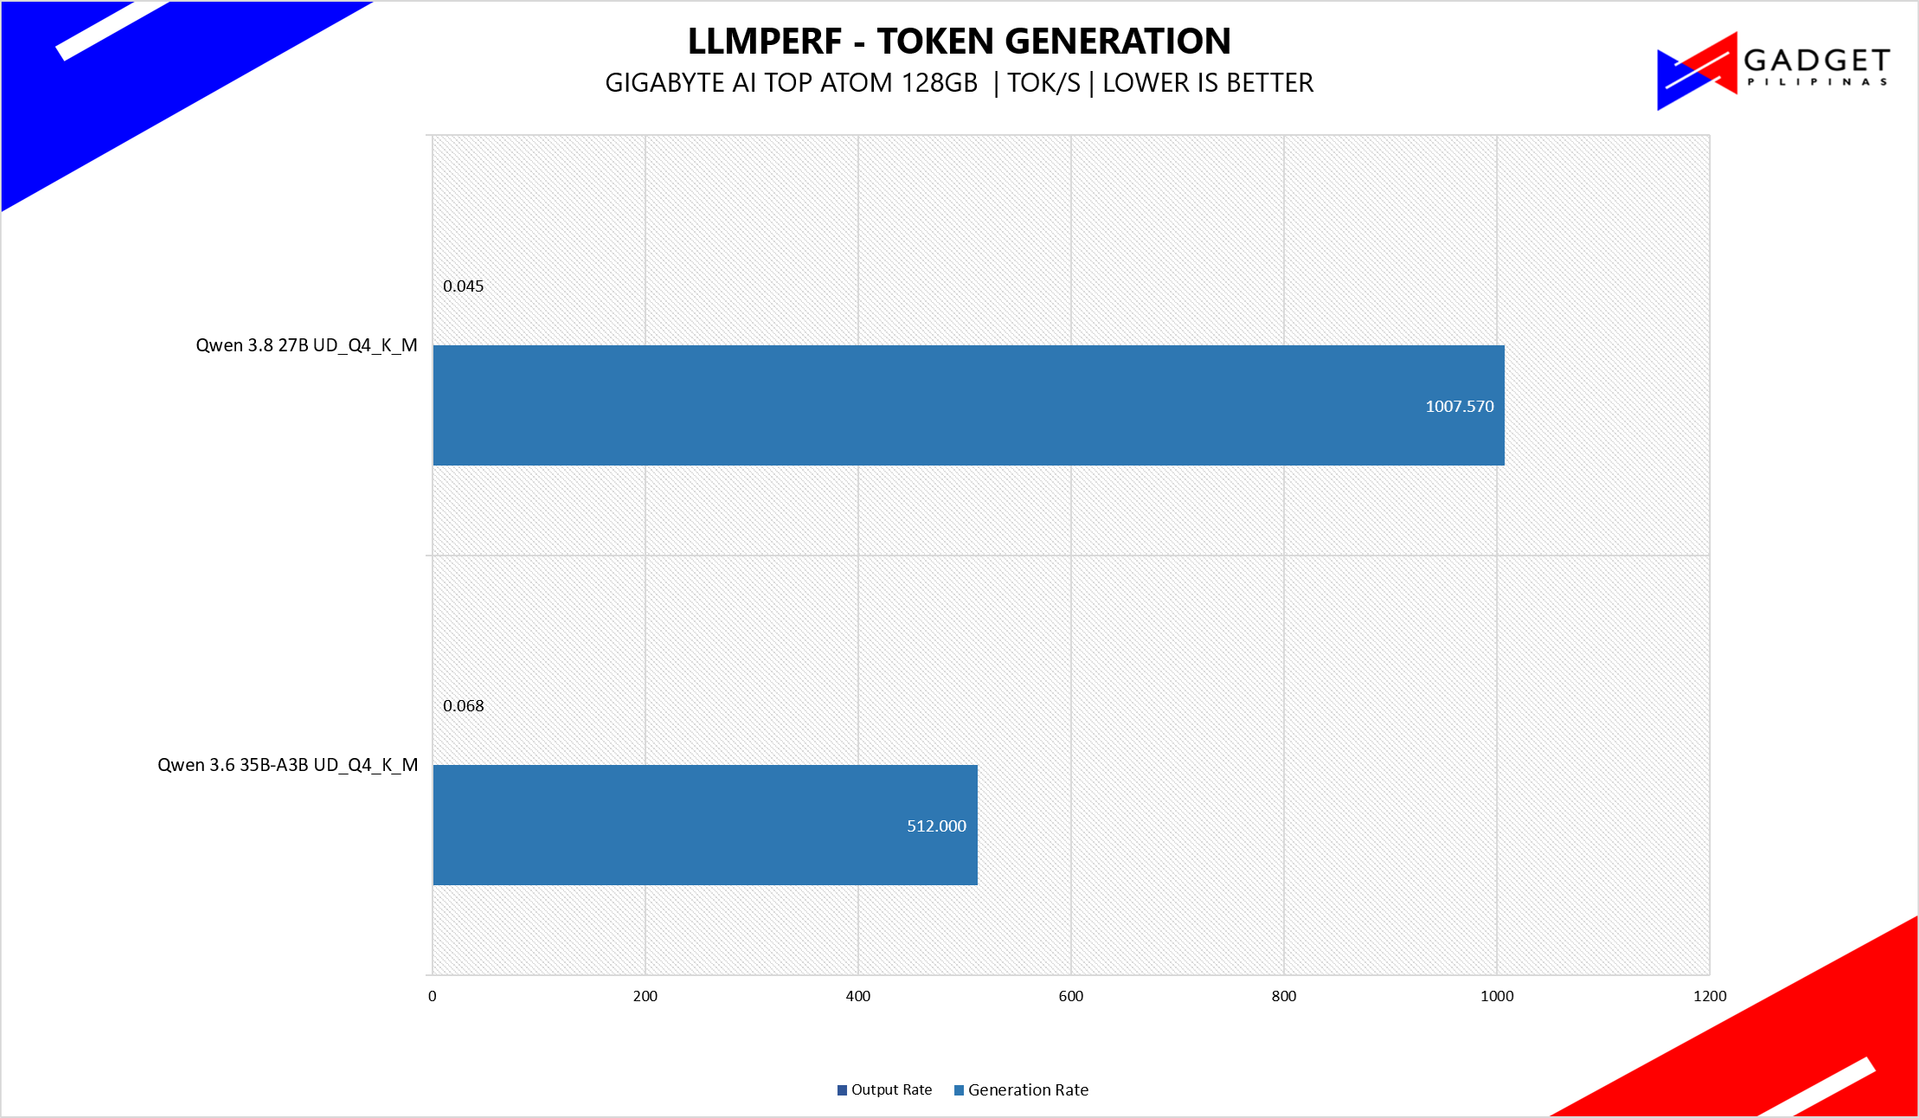
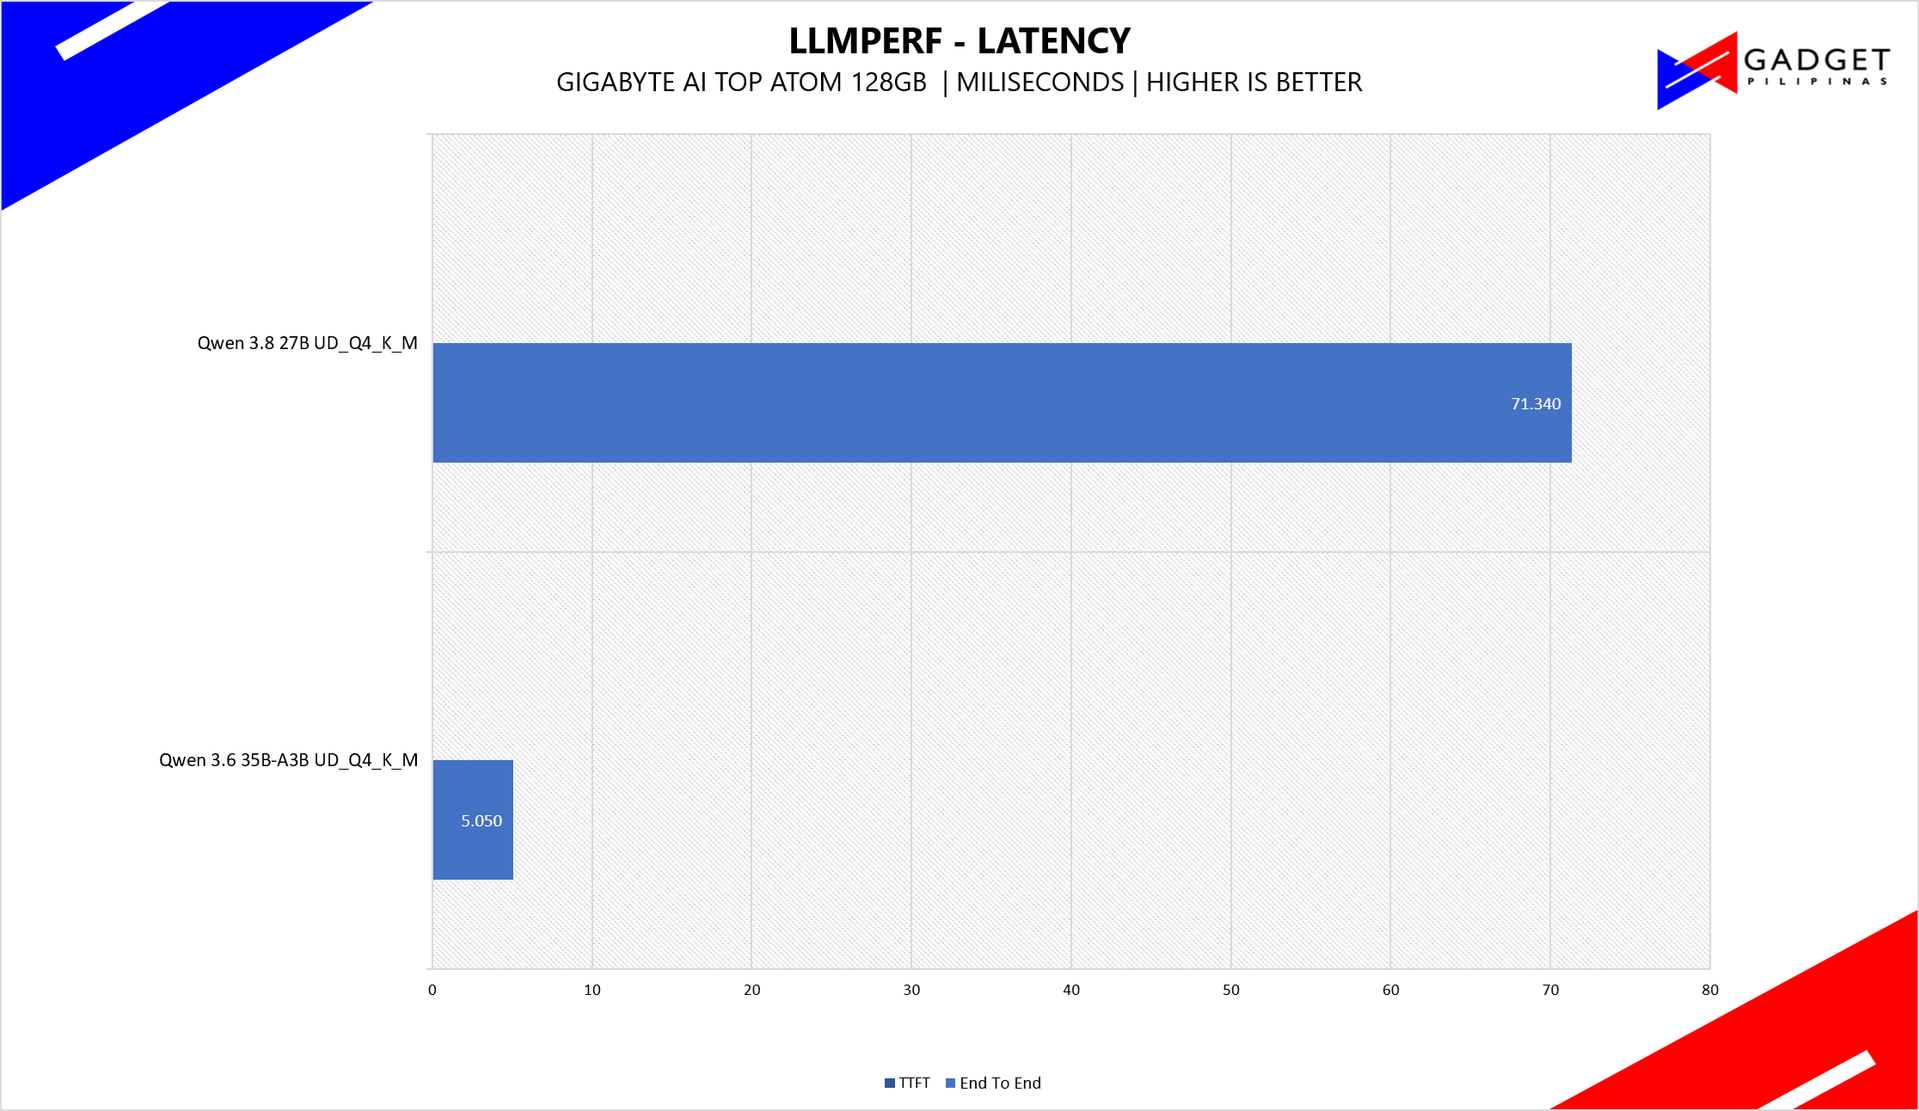
LLM perf measures request latency and throughput under a configured concurrent workload.
Conclusion: Weighing the Investment
The GIGABYTE AI TOP ATOM DGX SPARK brings decent compute and AI performance at the hands of a more “budget-oriented” individuals and businesses. By “budget-oriented” we mean business that can’t afford renting datacenters, or buying even the smallest server or commercial grade enterprise hardware for AI. The mere act of considering a DGX Spark purchase translates to a cost-benefit analysis of recurring cloud API costs or subscription fees versus a one-time, big-time payment.
If your organization handles proprietary client data, healthcare records, or sensitive financial modeling, shipping tokens across public cloud APIs simply isn’t an option due to rising costs, unstable token usage or privacy. In that operational environment, the DGX Spark makes immediate financial sense, especially in the long term. You get an enterprise-grade compute node in a manageable footprint, paired with a turnkey software layer that spares your developers from spending their initial deployment days troubleshooting. For dedicated research cells and boutique AI firms running continuous local training, fine-tuning passes, and batch inference, the ability to amortize a fixed hardware investment against unpredictable, recurring cloud compute bills quickly justifies the asking price despite the rising costs in hardware.
The DGX Spark premium means you’re paying for specialized memory architecture, orchestration overhead, and easy scalability that only pays dividends when the silicon is running 24/7 at full workload. If your daily workflow revolves around intermittent model testing, occasional prompt engineering, or standard workstation creative tasks, buying into this platform is overkill. For smaller independent creators or casual tinkerers, the math simply doesn’t pencil out when flexible, pay-as-you-go cloud instances remain drastically cheaper over the course of a year.
Ultimately, GIGABYTE has delivered a focused, well-engineered tool for teams ready to take full ownership of their AI infrastructure. As long as you have the persistent workloads to keep this silicon saturated and working almost 24/7 and the local pricing is lower than your projected cloud expenditure, then the GIGABYTE AI TOP ATOM DGX SPARK is a no-brainer asset to boost your business’ or team’s productivity without the complications of renting, running or maintaining server-grade AI infrastructure.
Grant Soriano
Grant is a Financial Management graduate from UST. His passion for gadgets and tech crossed him over in the industry where he could apply his knowledge as an enthusiast and in-depth analytic skills as a Finance Major. His passion allows him to earn at the same time help Gadget Pilipinas' readers in making smart, value-based decisions and purchases with his reviews and guides.
View all articles →Related Reviews
 MacBook Neo Long-Term Review: My Bedside Mac
 Sony 1000X The Collexion Review: Three Months Later
 ASUS ProArt P16 (H7607BA) Review: the RTX Spark platform, tested in the work creators actually do
 HONOR 600S Review: Bits of What’s Loved on the HONOR 600 Series in a More Accessible Package
 Keychron C75 HE 8K TMR Keyboard Review
 Samsung Galaxy S26 FE: Great Functional Elegance