Microsoft spent its October 7 Windows event reframing what a PC is for, and the useful part was not a new model but a new set of trade-offs. Local AI on RTX Spark, the NVIDIA superchip inside the laptops that opened for preorder that day, now means running near-frontier models on a machine you own, and getting the most out of it comes down to three things: enough unified memory, the right runtime, and a router that decides what stays on the device and what goes to the cloud.
What local AI on RTX Spark needs to run
Start with memory, because it decides which models are even possible. RTX Spark pairs a Blackwell RTX GPU of up to 6,144 cores with an up-to 20-core Grace CPU at 600 GB/s, up to 128GB of unified memory and as much as one petaflop of FP4 AI compute. NVIDIA says that is enough for models up to 120 billion parameters with a million-token context, and Microsoft says its Surface Laptop Ultra, which carries the same chip, runs models exceeding 120 billion parameters locally. A 16GB machine cannot join in: the models below need 20GB to 60GB before Windows takes its share.
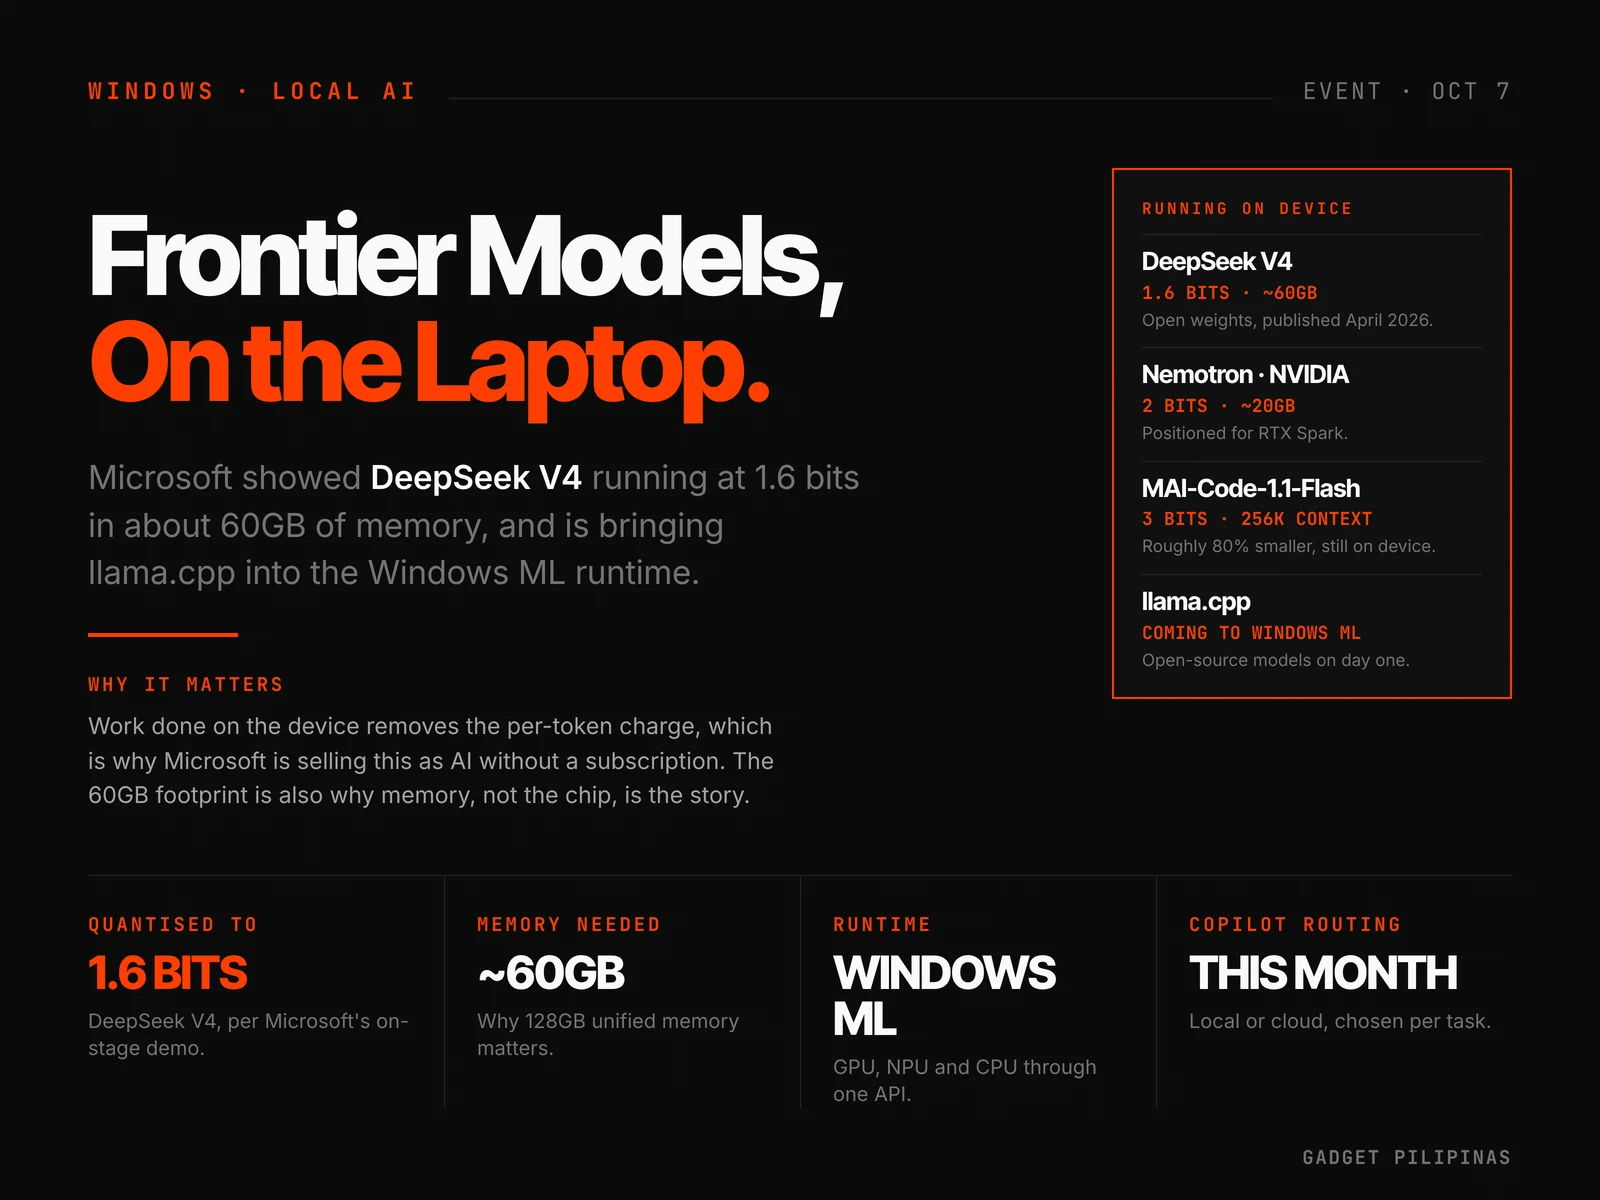
Then the runtime. Windows ML is the layer that deploys models across GPU, NPU and CPU through execution providers Microsoft manages and updates, and it has been generally available since September 2025. On October 7 Microsoft added llama.cpp support in Windows ML, which matters for a practical reason: it lets developers try open-source models as they land instead of waiting on a port.
The models worth planning around
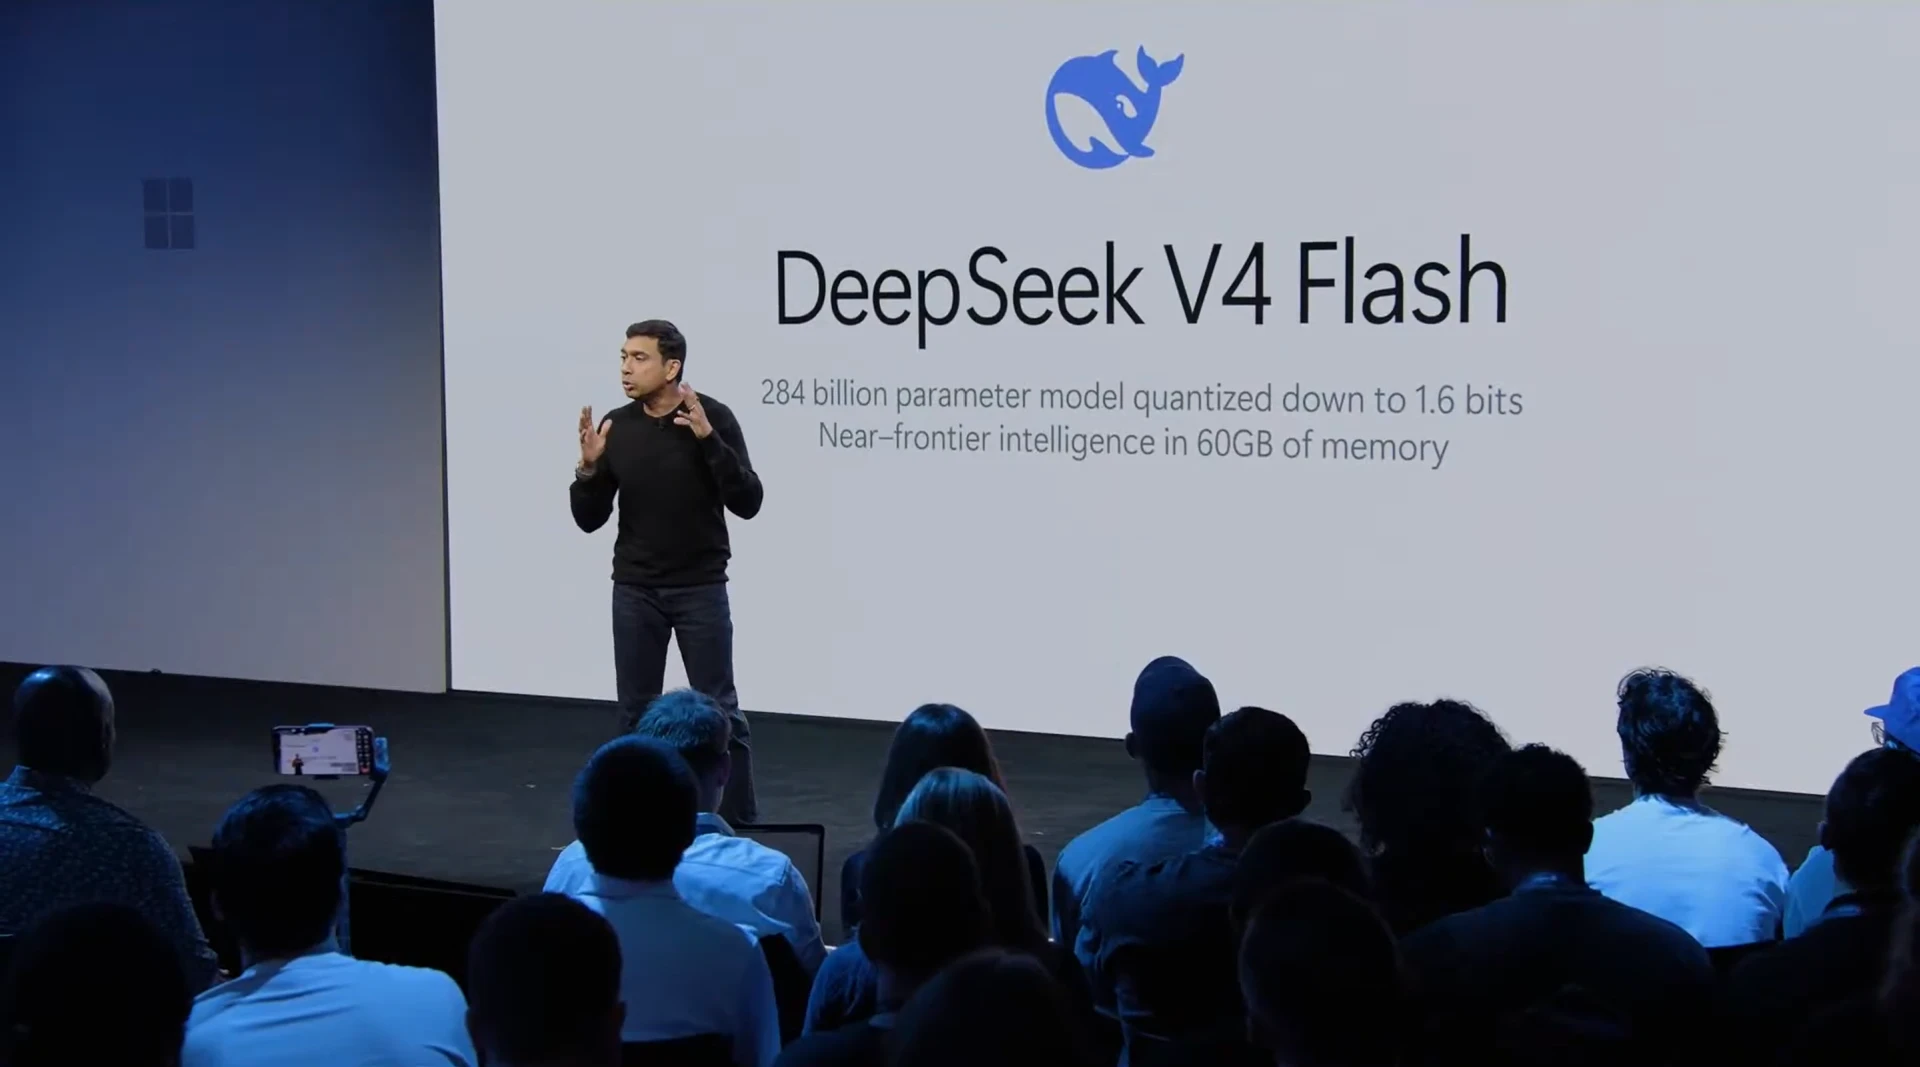
DeepSeek V4 Flash is the near-frontier option. It is a 284-billion-parameter model, and Microsoft showed it running locally at 1.6 bits inside roughly 60GB, which is the clearest evidence yet that a laptop can hold something close to the intelligence people currently pay a subscription for.
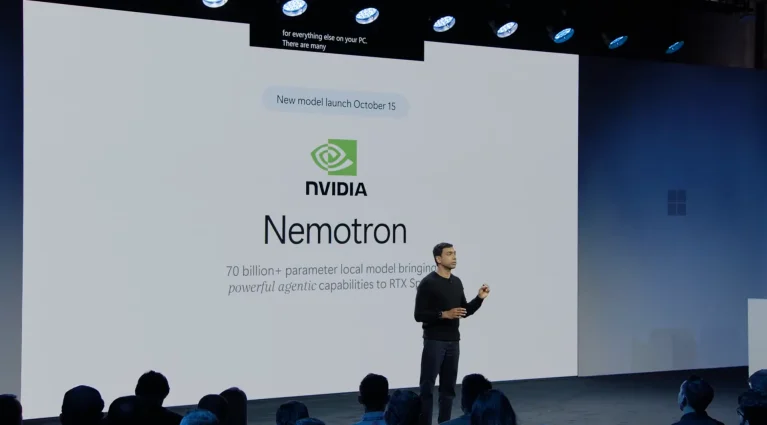
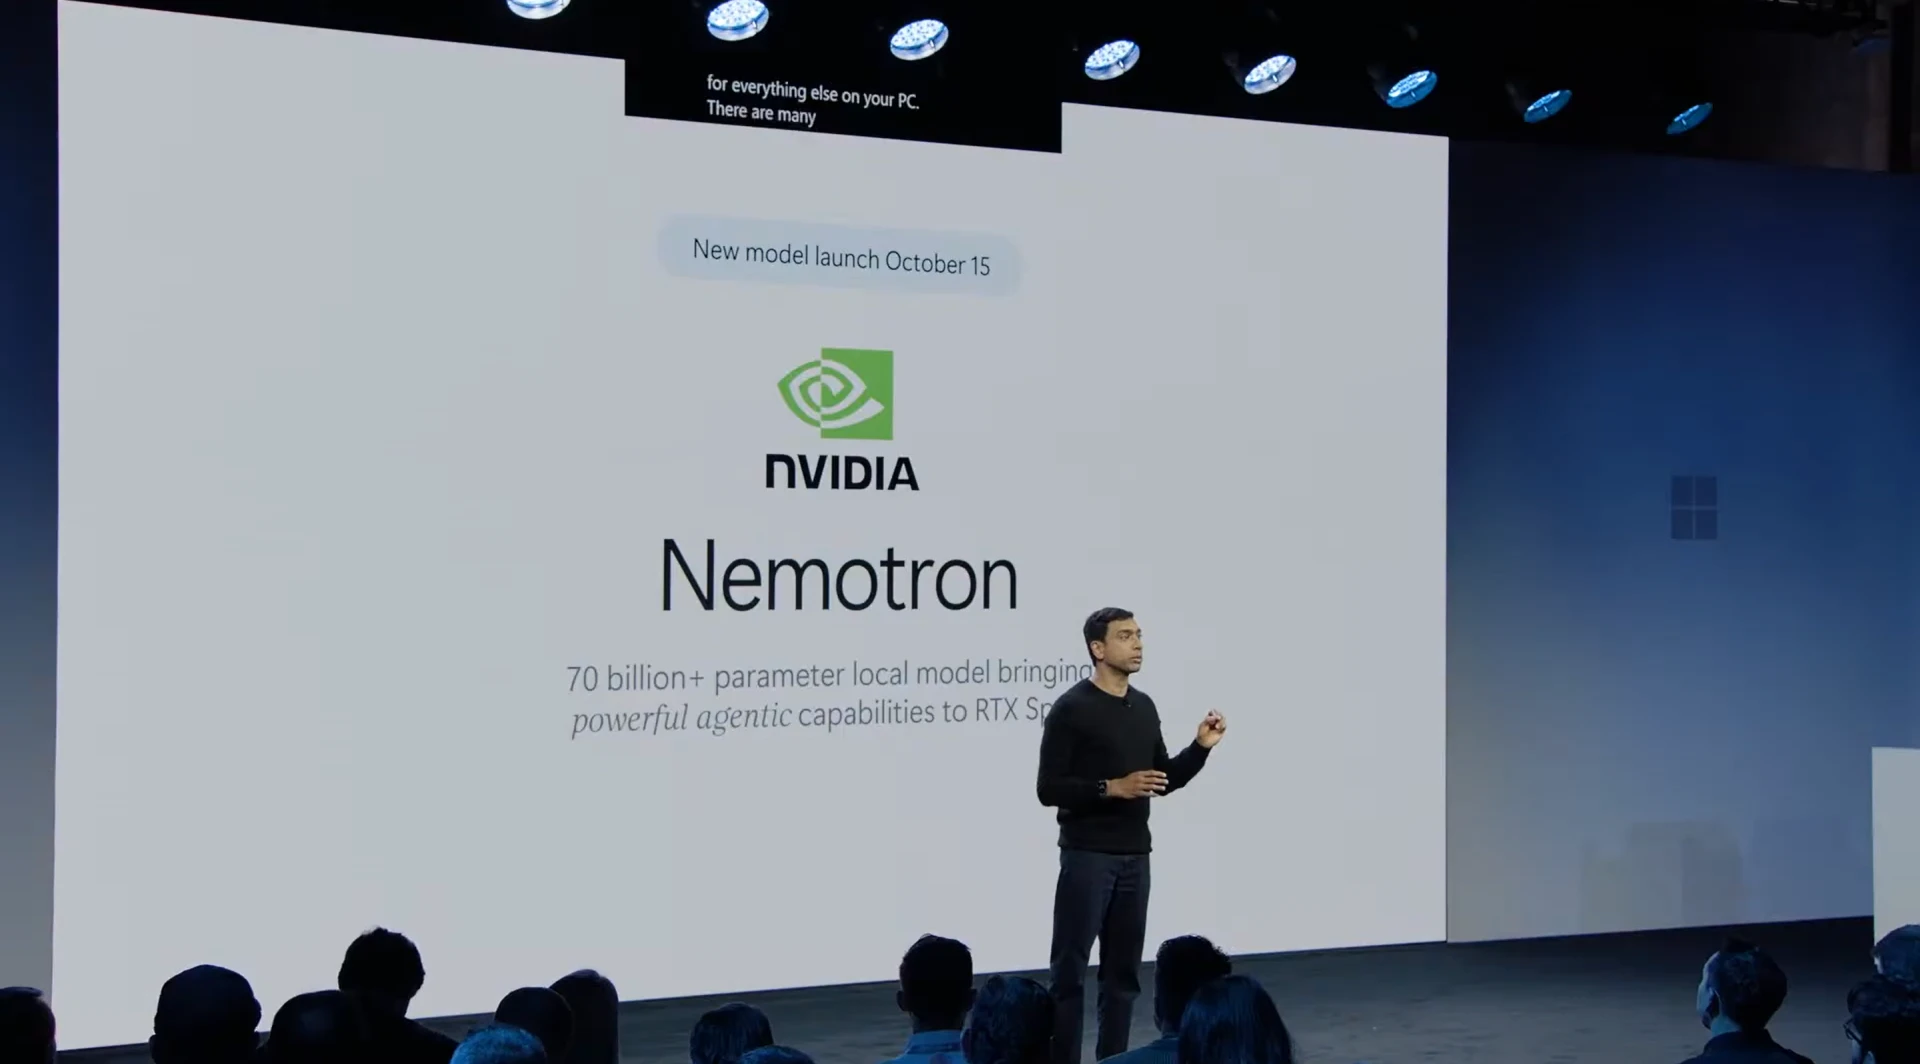
The model to watch is Nemotron. NVIDIA’s upcoming model has more than 70 billion parameters and is quantised to two bits so that it fits in just over 20GB, which is the specification that makes this practical on a laptop that is not a 128GB flagship. It’s set to be launched on October 15, and it is the one worth waiting for if you are buying below the top configuration.
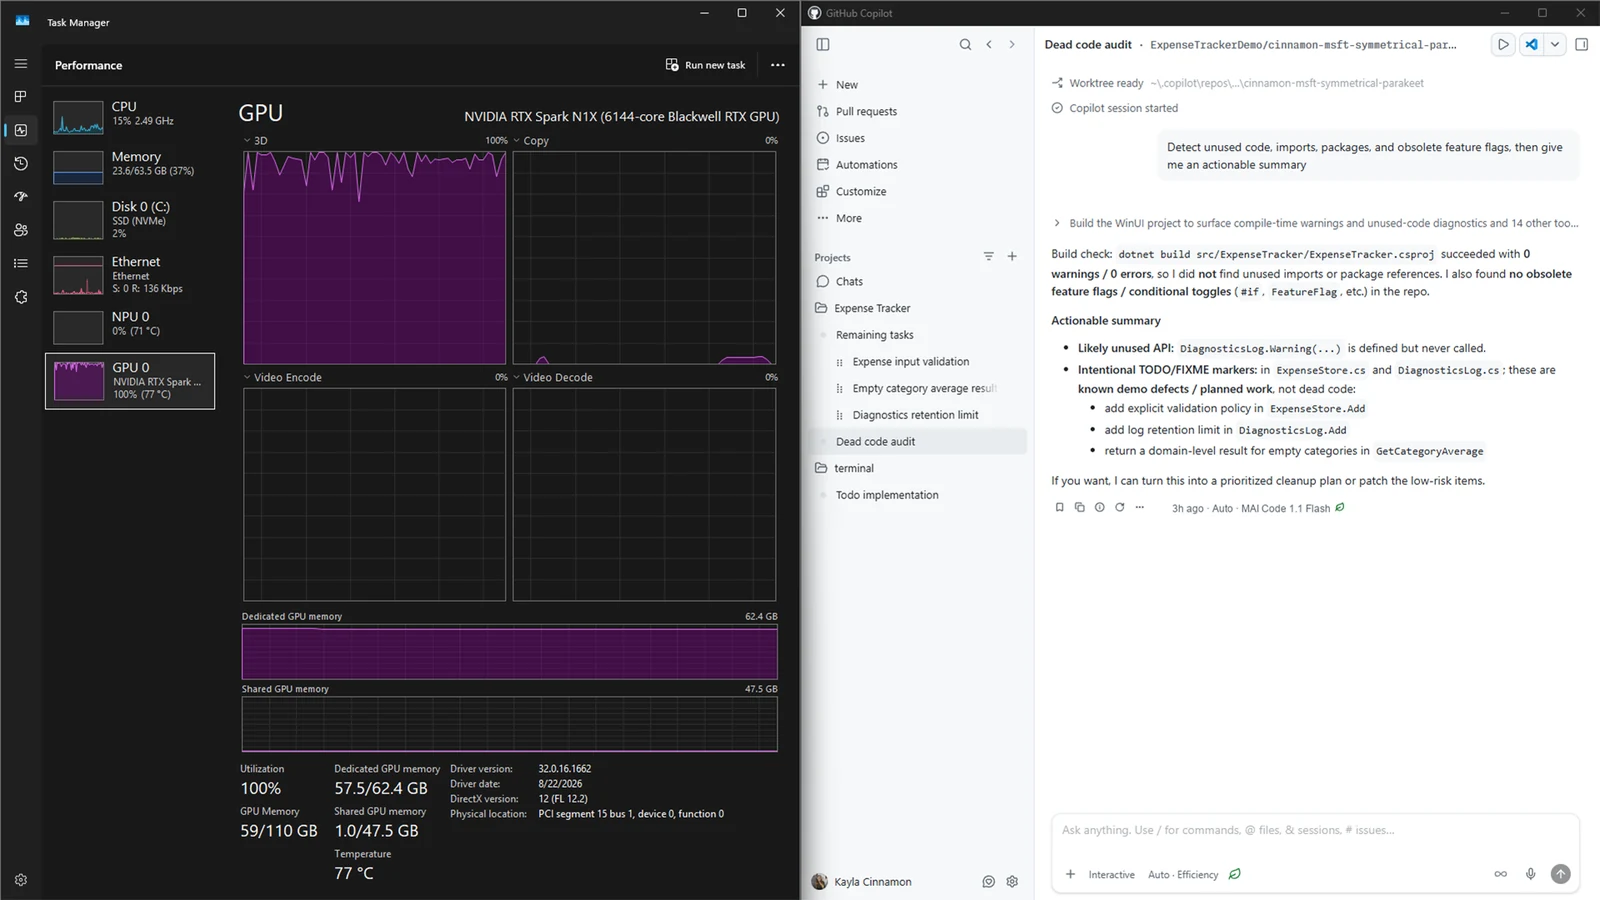
For coding, MAI Code 1.1 Flash is already there: 137 billion total parameters with 6.8 billion active, cut to three bits and nearly 80 percent smaller, running with a 256K context window on the device. NVIDIA adds Qwen 3.8 Flash Next, a 125-billion-parameter model with 51 billion active parameters that it says matches the intelligence of many cloud models, unmetered and without sending data anywhere.
Where the token savings come from
Local inference removes the per-token charge, and that is the whole pitch. The sentence the moderator pulled out of the coding demo was that you are getting these tokens for free. Microsoft put numbers on it: 1.6 million tokens processed by a local model returned 10,500, with no cloud credits spent, and an overnight automation was set to run the same way.
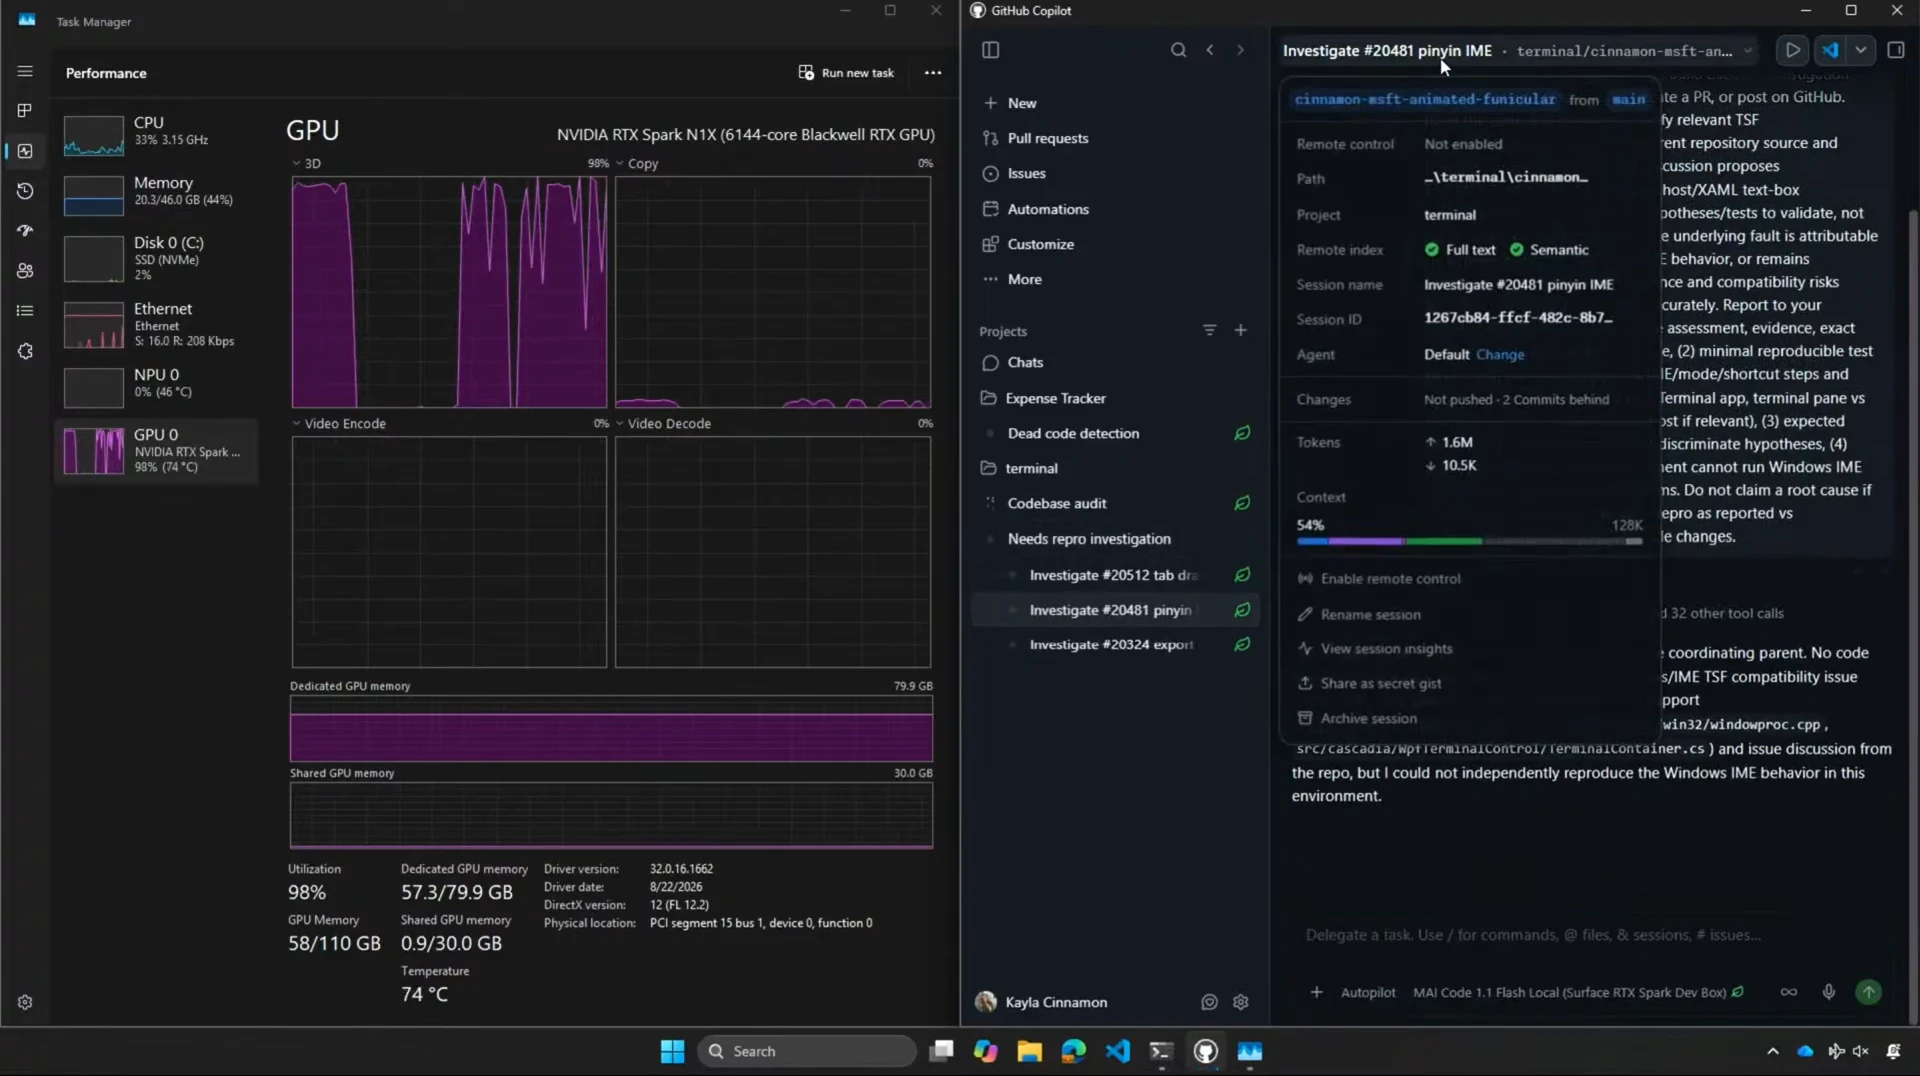
The saving is engineered in the routing. GitHub’s HydraFusion picks the right model for each task in the cloud, and Microsoft has extended it on Windows to reach models running on the device, so routine work can stay local and only the hard steps leave the machine. Microsoft’s blog puts the experimental preview in the GitHub Copilot app, the Copilot CLI and Visual Studio Code later in October, while the stage demo said hybrid intelligence reaches the Copilot app from October 15. Satya Nadella described the intent as seamless: “There will never be a moment where we will go and look and say, oh, this runs locally. This runs in the cloud.”
Microsoft frames the economics bluntly. As models grow, “customers’ needs are outpacing what their cloud budgets can support,” its Windows Experience blog says, and the goal is to make every AI token count. In practice that means keeping agent loops, file organisation, transcription and drafting on the machine, and paying for the cloud only when a task genuinely needs it.
Trust is the other half of the argument
Nadella opened the event by naming trust as the first of three pillars, and he did not treat it as a slogan. “There is no way to build any ecosystem without trust,” he said, adding later that “trust is where it all starts.”
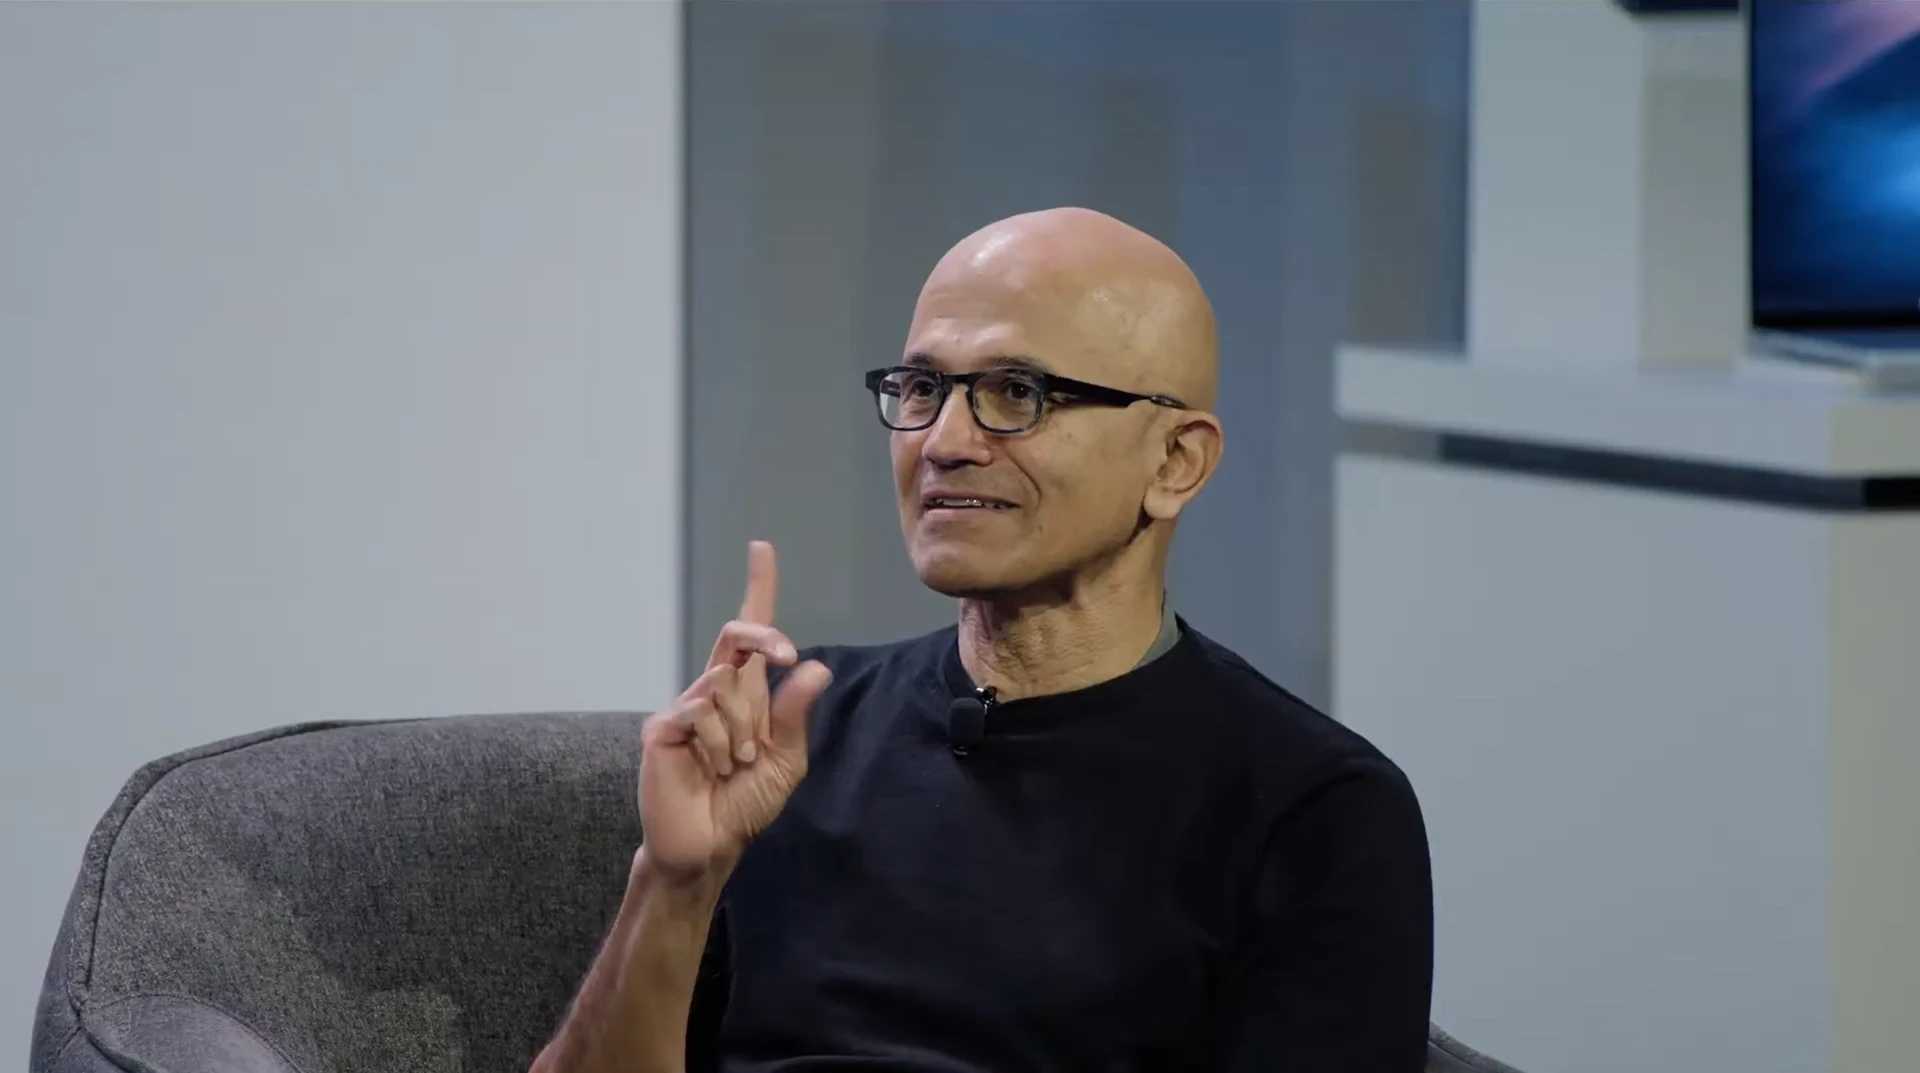
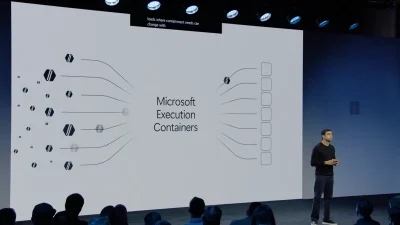
On a laptop that runs models locally, that promise takes two forms. The first is containment. Microsoft Execution Containers shipped to general availability on Windows 11 at the same event, giving agents their own identity, permission boundary and audit trail, enforced by Windows at runtime rather than by the app asking nicely. Nadella explained why it belongs in the operating system: “We need it to make the desktop the most secure place for agents to execute.” He added that agents need the same primitives the user gets: “I use the computer. My agents use the computer. The agents need these primitives as well.”
The second is that the data stays put. Copilot’s local context reads files and recent activity with your permission, local actions happen on your machine, and the clearest demo of the day had an agent gather scattered tax documents, rename and organise them and draft a reply without the documents leaving the device. Microsoft’s own phrasing is that you remain in control at every step, which is the consumer version of the same guarantee.
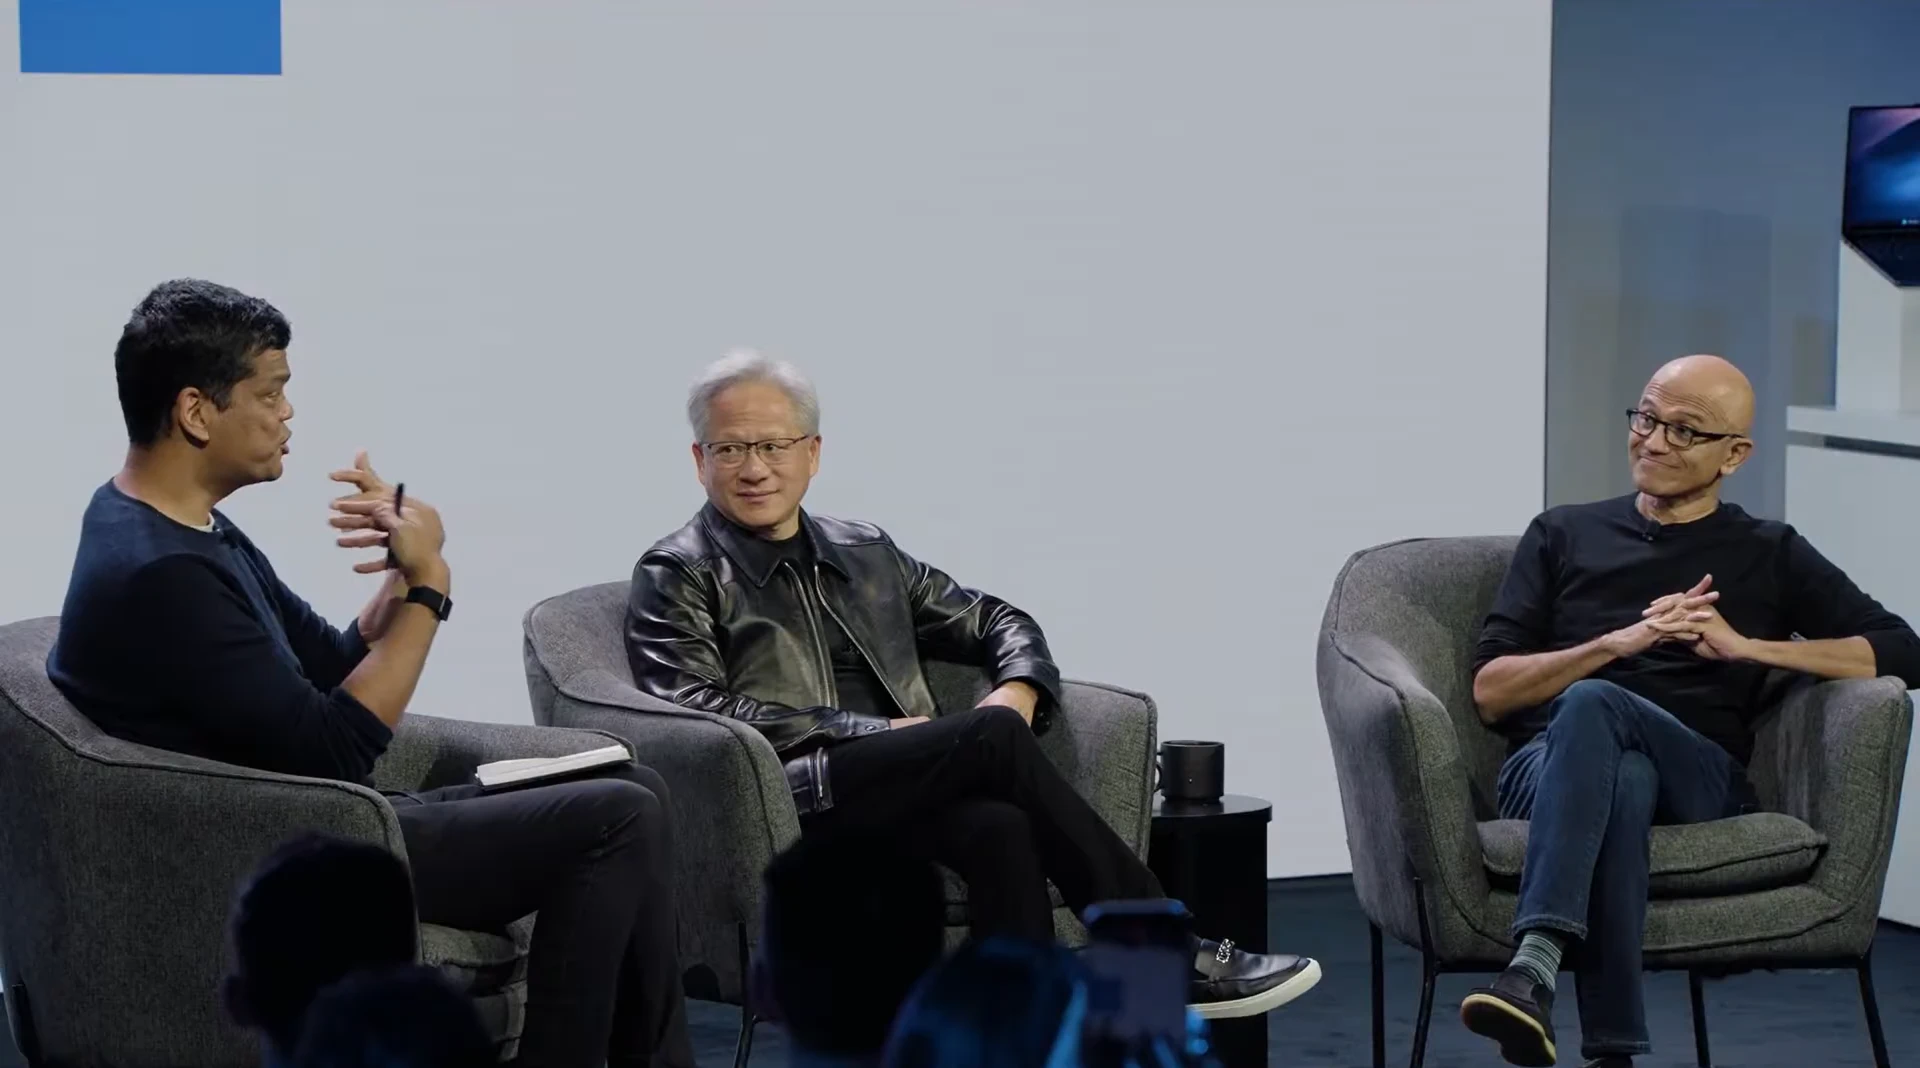
What remains unresolved is liability, and Nadella was candid about it. Asked who is responsible when an agent makes a purchase on your behalf, he pointed at economics rather than law: “Ultimately it’s going to be pricing, essentially the agent working on my behalf, and how does the marketplace price it.” Trust, in other words, is being sold as a property of the platform before it is settled as a question of responsibility.
What this means for buyers here
None of it changes the local maths yet. Microsoft has not announced Philippine pricing or availability for any RTX Spark device, so the practical advice for buyers in this market is to wait for the memory configuration and the local price to be published together: the 128GB machines are the ones that make this story real, and they will also be the most expensive.
We have covered the local-model hardware wave as it reached this market, from the GEEKOM mini PC that ships with DeepSeek on board to NVIDIA’s DGX Spark desktop and the Windows on Arm portables such as the Snapdragon X Elite Googlebook. The difference this week is that the models no longer have to be small to run without a subscription.
Sources: Microsoft Windows event, Windows Experience blog, NVIDIA event post, Microsoft command line blog, Foundry on Windows, Windows ML documentation, llama.cpp, DeepSeek.
Giancarlo Viterbo
Giancarlo Viterbo is a Filipino Technology Journalist, blogger and Editor of gadgetpilipinas.net, He is also a Geek, Dad and a Husband. He knows a lot about washing the dishes, doing some errands and following instructions from his boss on his day job. Follow him on twitter: @gianviterbo and @gadgetpilipinas.
View all articles →