

The Sony PlayStation 5 is probably one of the last few things you’d think if you want to run local AI models at home. Well, one redditor was able to make his Jailbroken PS5 run Qwen3.8 27B and managed to output 20 tokens per second. Reddit user u/AdIllustrious7246 was able to run this through his homebrew project PS5LM Plus that’s forked from another redditor, u/metover PS5LM project. PS5LM is a port of llama.cpp, making it able to run AI models natively on the PS5’s CPU. PS5LM Plus bring the local inference to the GPU with access to its unified memory architecture.
The breakthrough lands at a notable moment in the AI and gaming industry. With memory and storage supply shortage driving up RAM and SSD pricing across the whole industry, hackable PlayStation 5 consoles have already seen renewed interest and rising second-hand market prices. Now that the PS5 and its unified memory architecture is proven to be an AI-capable device, we’re expecting to see its prices rise further as AI enthusiasts a take interest with the gaming console.
PS5LM Plus – Running AI on your PS5
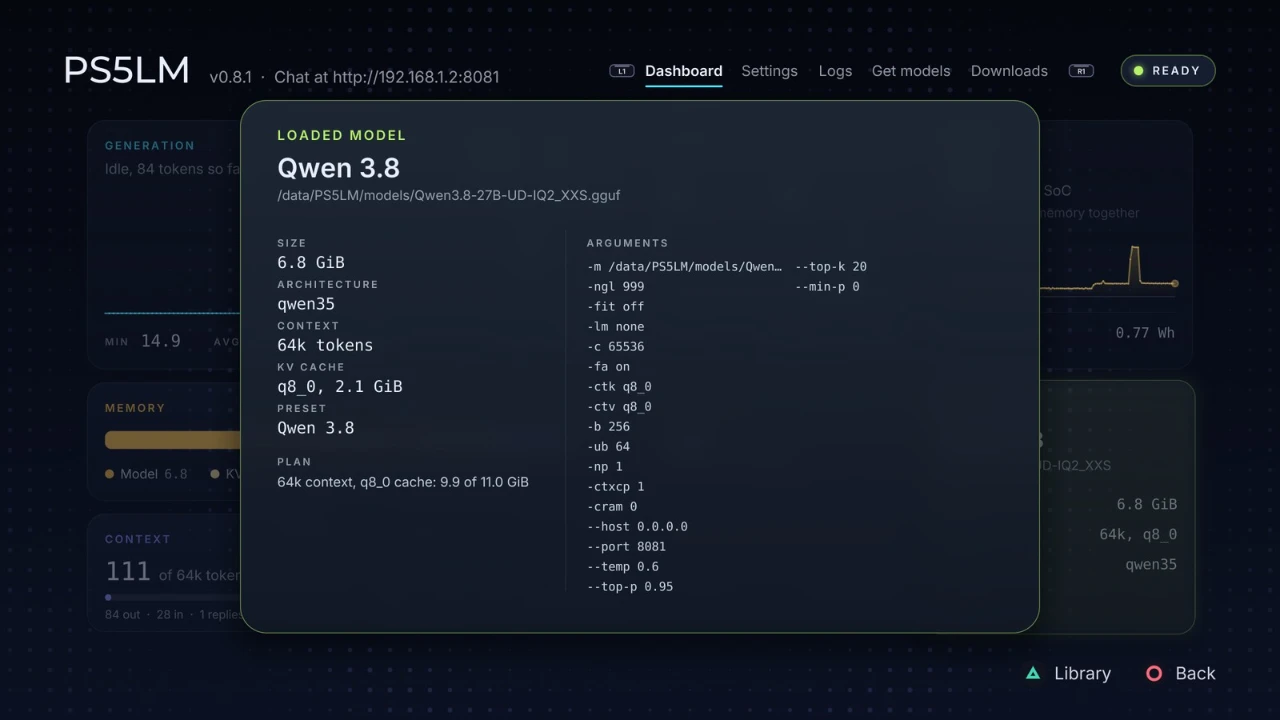
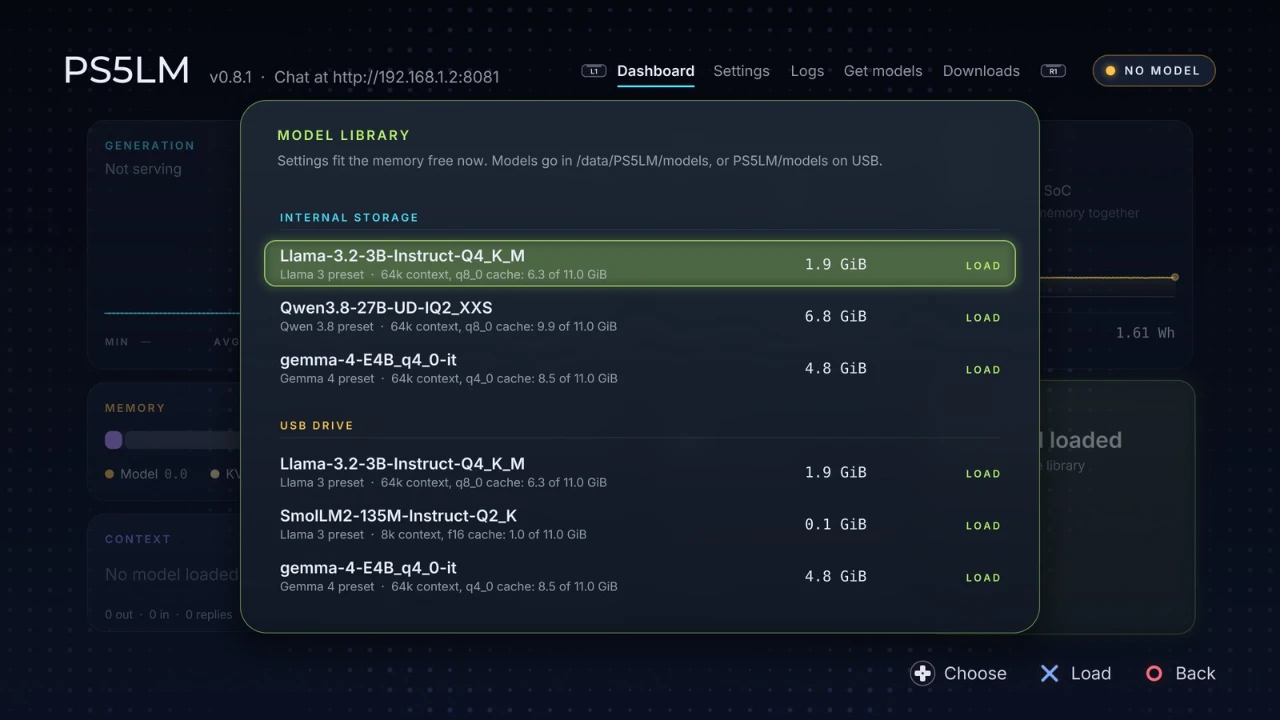
The original PS5LM implementation proved that llama.cpp could execute on the PS5’s operating environment, but it operated strictly as a background payload on the AMD Zen 2 CPU cores. PS5LM’s implementation capped accessible memory to roughly 6 GB and lacked GPU acceleration entirely. Using a dense model like Qwen 3.8 27B parameters from disk running on the CPU, token output crawled at approximately one token per minute. To solve the throughput bottleneck, u/AdIllustrious7246 restructured the application from a background payload into a native PS5 title (an fSELF executable) registered via ShadowMountPlus.
Operating as a native application unlocks direct access to the console’s 12 GB unified memory pool, yielding approximately 11.4 GB of usable memory space for models and KV caches.PS5LM Plus links llama-server to the ggml Vulkan backend via developer Mihawk-99’s RADV Vulkan port (PS5_Vulkan), enabling GPU compute. Because the console presents its physical memory as a unified pool, the software operates inside a single 12 GB device heap, similar to the how Macbooks and the new RTX Spark access their unified memory.
PlayStation 5 Feasibility with AI
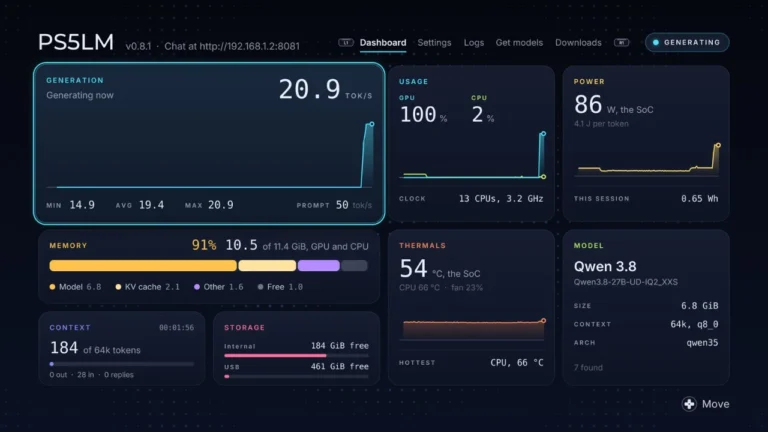
Hitting 20.7 tokens per second on Qwen 3.8 27B makes local AI genuinely usable on the PS5. That said, an aggressive UD-IQ2_XXS 2-bit quantization, shrinking the model to 6.8 GBs so that 64k context could fit is needed to make it usable. While the standard 8 GB or 12 GB desktop PC GPUs can’t run a dense 27B model, the PS5’s unified architecture keeps the entire workload running directly on the GPU. You do sacrifice some output precision by dropping to 2-bit weights, but it proves the console can realistically double as a capable local inference machine. Here are the complete
- Qwen 3.8 27B UD-IQ2_XXS, 6.8 GB: Operating with a 64k context window and a q8_0 KV cache, the model clocked 20.7 tokens per second on the PS5 GPU. A slightly heavier quantization, Qwen 3.8 27B UD-Q2_K_XL (9.2 GB), achieved 20.3 tokens per second with a 32k context window and q4_0 cache (averaging 19.7 tok/s across a continuous 7,775-token generation).
- Gemma 4 E4B QAT Q4_0, 4.8 GB: Loaded directly from external USB storage with a 64k context window and q4_0 cache, the model generated at 61 tokens per second.
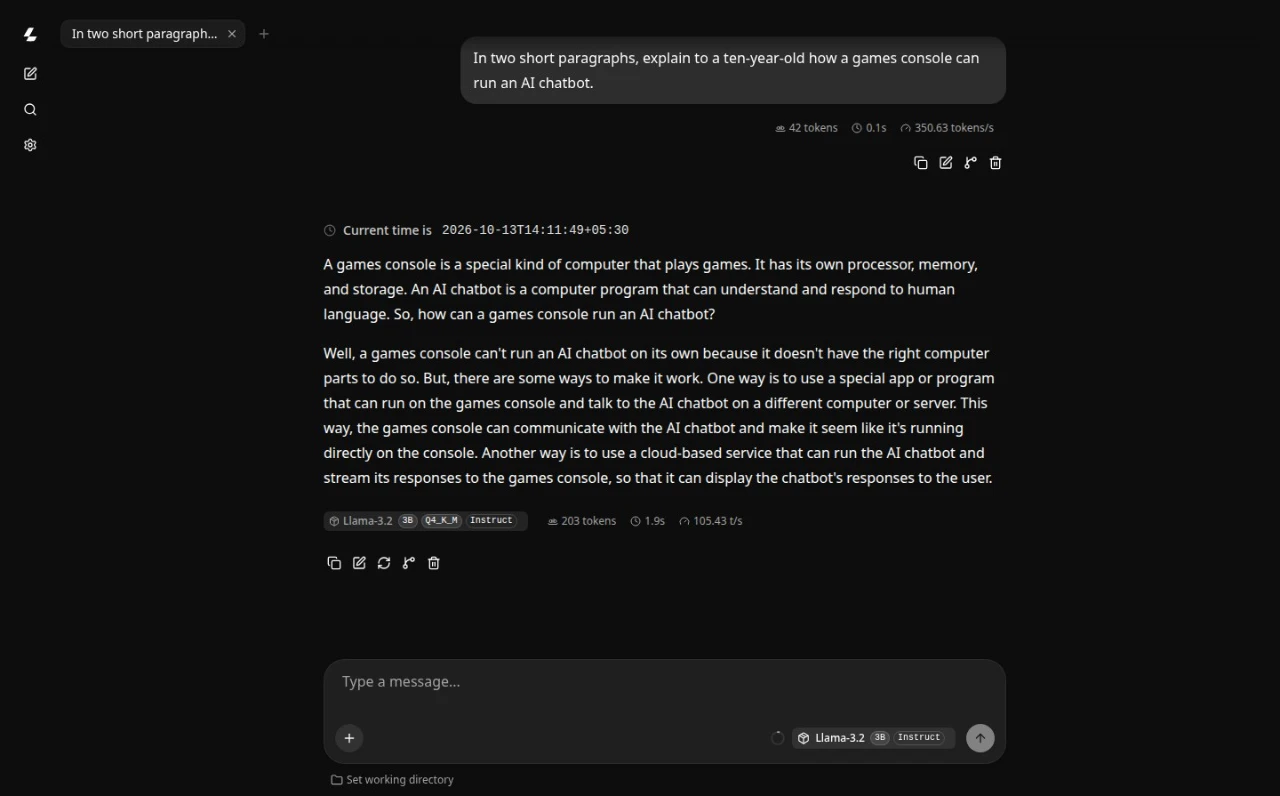
- Llama 3.2 3B Instruct Q4_K_M, 1.9 GB: Running from USB storage with a 64k context window and q4_0 cache, generation throughput hit 124 tokens per second. In standalone browser chat testing over the local network, the model delivered prompt-ingestion speeds above 350 tokens per second and sustained generation speeds of 105.43 tokens per second.
Because native titles on the PS5 cannot completely flush memory without lingering allocations—leaving roughly 5 GB retained when attempting an in-place swap—PS5LM Plus automatically reboots the application whenever the user switches models to keep the full memory pool clean.
On-Screen Dashboard, Direct Downloads, and Network API
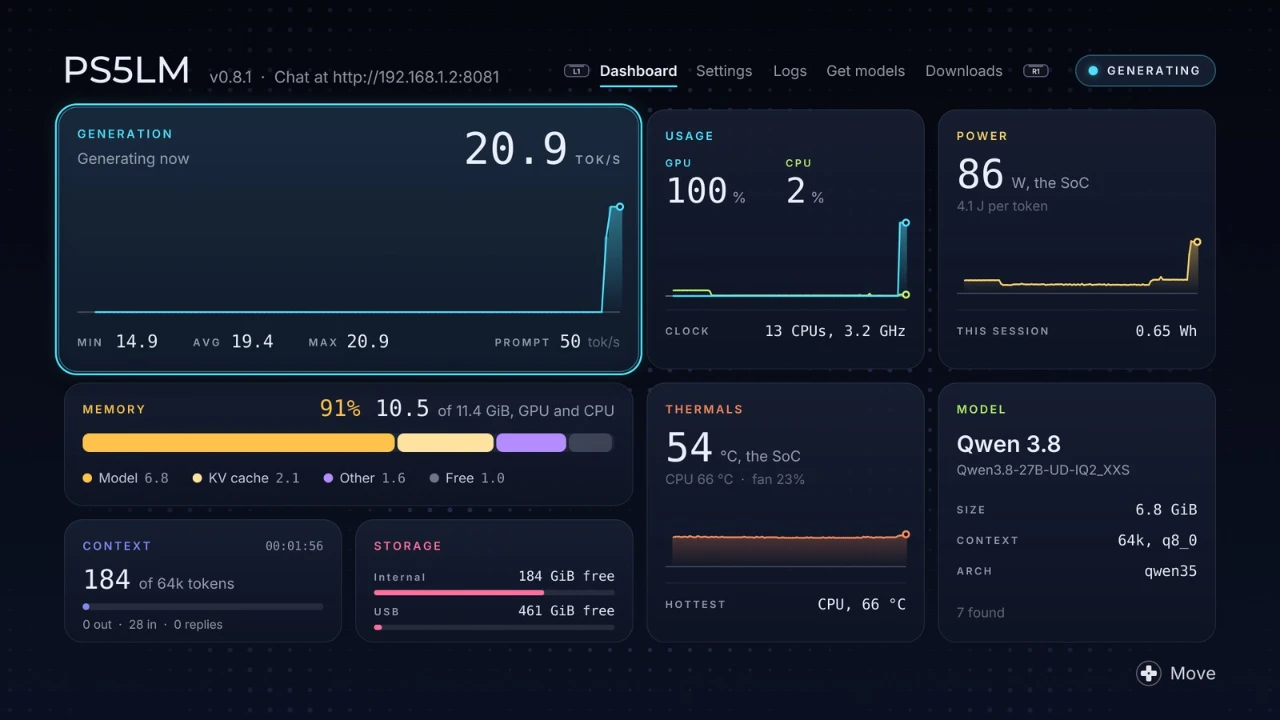
Rather than relying strictly on command-line terminal scripts, PS5LM Plus packages the engine into a TV-friendly interface built with ps5-homebrew-ui over ps5-opengl. The dashboard provides real-time telemetry, including active token rates, CPU and GPU utilization, memory allocation splits (model weights versus KV cache), and drive capacity across internal and external storage. To bypass sandboxed title restrictions that prevent reading hardware sensors, the app pulls power draw, SoC wattage, and fan speeds via a companion payload called ps5-exporter.
Other features of PS5LM Plus include:
- Storage Flexibility: Models formatted in standard .gguf containers can be loaded directly from internal storage, an expanded M.2 NVMe SSD, or external USB drives without requiring manual transfers.
- Integrated Hugging Face Downloader: Users can search and pull
.ggufweights directly from Hugging Face repositories on the console. The downloader inspects the initial 16 MiB of a file to check whether the model fits inside free system memory before starting, and handles network traffic using Sony’s nativelibSceHttp2and libSceSsl libraries with resume support and SHA-256 verification. - Automated Memory Planning: When selecting a model, the software automatically calculates and configures the longest viable context window and optimal KV cache quantization (q4_0 or q8_0) that fits within free memory.
- Local Network Serving: The app hosts llama.cpp’s web interface over the local network at http://<console_ip>:8081. It also exposes OpenAI-compatible Chat Completions and Anthropic Messages API endpoints, enabling developers to connect external developer tools like Claude Code, opencode, codex, and aider directly to the console. Vision capabilities are also supported when pairing compatible multimodal models, such as Gemma 4, with their corresponding projection files.
PS5LM Plus Installation Requirements
To run PS5LM Plus, users require a jailbroken PlayStation 5 console running firmware compatible with the etaHEN homebrew environment, kstuff, and the ShadowMountPlus utility, with elfldr and ftpsrv recommended for setup and payload management.
u/AdIllustrious7246 has submitted the initial native application build as a pull request (cobanov/PS5LM#12) to Cobanov’s upstream repository. In the interim, the complete project source code, deployment scripts, and documentation are available under the GPL-3.0 license on GitHub via the abhi245y/PS5LM-Plus repository.
PS5LM Plus Technical Profile & Tested Model Performance
| Model Architecture | File Size | Quantization | Context Window | KV Cache Type | Documented Speed |
|---|---|---|---|---|---|
| Qwen 3.8 27B | 6.8 GB | UD-IQ2_XXS | 64k tokens | q8_0 (2.1 GB) | ~20.7 tok/s |
| Qwen 3.8 27B | 9.2 GB | UD-Q2_K_XL | 32k tokens | q4_0 | ~20.3 tok/s (19.7 avg) |
| Gemma 4 E4B | 4.8 GB | QAT q4_0 | 64k tokens | q4_0 | ~61 tok/s |
| Llama 3.2 3B Instruct | 1.9 GB | Q4_K_M | 64k tokens | q4_0 | ~124 tok/s |
| Qwen 3.8 27B (CPU Payload Baseline) | — | — | — | — | ~1 token / minute |
Frequently Asked Questions (FAQ)
Can a Sony PlayStation 5 run local AI models?
Yes. A jailbroken PlayStation 5 can run large language models locally via PS5LM Plus, an open-source homebrew port of llama.cpp. Unlike earlier CPU-only experiments, PS5LM Plus runs as a native title that uses the console’s AMD RDNA 2 GPU and unified memory architecture to process AI models entirely on-device without an internet connection.
How fast does local AI models run on a jailbroken PS5?
Inference performance varies by model size and quantization, with documented speeds reaching:
- Qwen 3.8 27B (UD-IQ2_XXS): ~20.7 tokens per second (with a 64k context window).
- Gemma 4 E4B (QAT q4_0): ~61 tokens per second.
- Llama 3.2 3B Instruct (Q4_K_M): ~124 tokens per second on-device (and over 105 tokens/s over the local web UI).
How does the PS5 run a dense 27-billion parameter model?
The PS5 features a unified memory architecture where the CPU and GPU share a single memory pool. Running as a native title grants PS5LM Plus direct access to roughly 11.4 GB of usable high-bandwidth memory. When compressed using aggressive 2-bit quantization (UD-IQ2_XXS), the Qwen 3.8 27B model shrinks to 6.8 GB, allowing both the model and a 64k context cache to run entirely on the GPU without the PCIe bus transfer bottlenecks seen on standard 8 GB or 12 GB desktop PC graphics cards.
What are the trade-offs of running local LLMs on a PS5?
The primary compromise is model precision. Squeezing a dense 27B model into the console’s ~11.4 GB memory ceiling requires 2-bit quantization (UD-IQ2_XXS), which sacrifices output accuracy compared to higher bit-depths. Additionally, native PS5 titles cannot fully release memory during in-place swaps, requiring the app to reboot whenever you switch between different models.
What software is required to run PS5LM Plus?
To run PS5LM Plus, users need a jailbroken PS5 console equipped with:
- etaHEN homebrew environment
- kstuff
- ShadowMountPlus (to register the homebrew app as an fSELF title)
- Recommended:
elfldrand ftpsrv for file transfers and payload management
Grant Soriano
Grant is a Financial Management graduate from UST. His passion for gadgets and tech crossed him over in the industry where he could apply his knowledge as an enthusiast and in-depth analytic skills as a Finance Major. His passion allows him to earn at the same time help Gadget Pilipinas' readers in making smart, value-based decisions and purchases with his reviews and guides.
View all articles →